<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://danielagduca.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://danielagduca.github.io/" rel="alternate" type="text/html" /><updated>2024-10-09T15:15:32+00:00</updated><id>https://danielagduca.github.io/feed.xml</id><title type="html">Dr Daniela Duca</title><subtitle>Musings about art, technology, research, and some paintings.</subtitle><author><name>Daniela Duca</name></author><entry><title type="html">Universities need more than off-the-shelf AI solutions</title><link href="https://danielagduca.github.io/tools%20&%20technology/ai-higher-ed/" rel="alternate" type="text/html" title="Universities need more than off-the-shelf AI solutions" /><published>2024-06-05T00:00:00+00:00</published><updated>2024-06-05T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/ai-higher-ed</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/ai-higher-ed/"><![CDATA[<p>This post was originally published on the <a href="https://blogs.lse.ac.uk/impactofsocialsciences/2024/06/05/universities-need-more-than-off-the-shelf-ai-solutions/">LSE Impact Blog</a>.</p>

<blockquote>
  <h2 id="excerpt">Excerpt</h2>
  <p>Following the release of ChatGPT Edu, OpenAI’s enterprise offer to universities, Daniela Duca assesses the landscape of AI adoption in higher education and the different and emerging AI options ava…</p>
</blockquote>

<p>Last week, OpenAI unveiled <a href="https://openai.com/index/introducing-chatgpt-edu/">ChatGPT Edu</a>, an enterprise offering developed through a collaborative effort with institutions like Arizona State University, marking their first foray into sector-specific solutions. However, the increased token limits and enhanced security, while appealing, may not be enough to significantly accelerate the adoption of generative AI across higher education.</p>

<p>At present most universities likely fall into one of three categories:</p>

<h3 id="innovators">Innovators</h3>

<p>These trailblazers have already partnered with OpenAI, Microsoft, or developed their own custom solutions using open-source models. These <a href="https://www.insidehighered.com/news/tech-innovation/artificial-intelligence/2024/03/21/universities-build-their-own-chatgpt-ai">include</a> <a href="https://newsroom.asu.edu/press-release/arizona-state-university-collaboration-openai-charts-future-ai-higher-education">Arizona State University</a>, the <a href="https://genai.umich.edu/">University of Michigan</a>, the <a href="https://utk.teamdynamix.com/TDClient/2277/OIT-Portal/KB/ArticleDet?ID=148577">University of Tennessee Knoxville</a>, <a href="https://news.uci.edu/2024/03/18/uc-irvine-launches-customized-generative-artificial-intelligence-tool/">UC Irvine</a>, <a href="https://lil.law.harvard.edu/blog/2024/02/12/warc-gpt-an-open-source-tool-for-exploring-web-archives-with-ai/">Harvard</a> <a href="https://huit.harvard.edu/ai-sandbox">University</a>, <a href="https://www.it.northwestern.edu/about/news-events/2024/microsoft-copilot-available-university-community.html">Northwestern University</a>, <a href="https://www.studlife.com/news/2024/01/31/washington-university-launches-its-own-version-of-chatgpt">Washington University</a>, <a href="https://info.lse.ac.uk/staff/divisions/Eden-Centre/Artificial-Intelligence-Education-and-Assessment/School-guidance">LSE</a> and probably a few others.</p>

<h3 id="stewards">Stewards</h3>

<p>This group has been actively developing comprehensive guidelines as they explore institution-wide adoption. They’re utilising tools like Microsoft Copilot for administrative tasks and may be about to roll out solutions specifically for teaching and learning or research. Many universities, including Delaware, UT Austin, Cornell, <a href="https://www.library.cmu.edu/about/news/2024-04/ai-literacy-hackathon">Carnegie Mellon</a>, and several <a href="https://ocul.on.ca/ocul-taskforce-ai-announcement">Canadian institutions</a> like Queen’s, Ottawa, Wilfrid Laurier, McMaster, Toronto Met, and Western, are in this category. The Russell Group institutions in the UK developed <a href="https://russellgroup.ac.uk/media/6137/rg_ai_principles-final.pdf">a series of principles</a>, providing extensive guidance and resources on AI across the consortium.</p>

<h3 id="the-hmm-crew">The hmm… crew</h3>

<p>Finally, many medium- and small-size institutions might be still pondering their options or simply waiting. The <a href="https://library.educause.edu/resources/2024/2/2024-educause-ai-landscape-study">Educause AI landscape report</a> reveals that a significant 11% of institutions (respondents) haven’t even begun strategising about AI integration.</p>

<p>So, which genAI flavour will campuses choose?</p>

<p>With ChatGPT Edu, there are now three major enterprise off-the-shelf options: Microsoft Copilot, Google Gemini, and OpenAI’s offering. The challenge for larger institutions lies in enabling seamless access across the entire campus. Microsoft and Google have made this relatively easy, but ChatGPT still presents a hurdle, potentially becoming yet another app to manage. However, its sheer brand recognition might prevent it from getting lost in the shuffle.</p>

<blockquote>
  <p>With ChatGPT Edu, there are now three major enterprise off-the-shelf options: Microsoft Copilot, Google Gemini, and OpenAI’s offering</p>
</blockquote>

<p>A more intriguing option, in my opinion, lies in universities leveraging their research prowess and deep expertise in teaching and learning to build custom solutions. Open source models are becoming increasingly sophisticated, and readily available through various cloud platforms. The <a href="https://www.ibm.com/products/watsonx-ai">simplified building of retrieval-augmented solutions</a> (RAGs), which allows <em>Large Language Models (LLMs) to access specific information in real-time to answer user queries and can be used to create research assistants powered by an institutions own data, and</em> <a href="https://youtu.be/sal78ACtGTc?si=6oOKdbOPWJ5UWTJ4">advancements in agentic systems</a>, which <em>offer an alternative architecture to building generative AI assistants consisting of multiple LLM-powered agents, both contribute to</em> making the development and use of open source AI systems a tempting prospect for institutions with the requisite expertise.</p>

<p>An open source approach aligns well with the ethos of universities and potentially offers more effective and tailored tools. However, it’s undeniably a massive undertaking for most institutions. One promising path forward involves consortia of universities collaborating on such tools and services, potentially led by the Innovators or established sector leaders<strong>,</strong> who have already built custom solutions. Australia, for example, has successfully implemented a similar system for <a href="https://riconnected.org.au/">research and data services</a>, while the UK has led the way with shared cloud infrastructure. The recently announced <a href="https://www.acenet.edu/Documents/Global-Data-Consortium-Working-Draft.pdf">Global Data Consortium</a> also aims to bring universities together around the use of AI on student data. This collaborative model could help distribute costs and expertise, making this ambitious endeavor more feasible for a wider range of institutions.</p>

<blockquote>
  <p>An open source approach aligns well with the ethos of universities and potentially offers more effective and tailored tools.</p>
</blockquote>

<p>However, it’s not simply security concerns and technical integration hindering enterprise adoption of generative AI in higher education. It’s also about familiarity. We haven’t quite figured out the best way to use genAI at the institutional level, given its inherent limitations.</p>

<h2 id="whats-the-point-of-genais-for-universities">What’s the point of GenAIs for universities?</h2>

<p>A recent poll conducted on Sage’s Research Methods Community (Fig.1) reveals that 57% of social science researchers and faculty have not yet used generative AI, while another 13% are interested but haven’t taken the plunge. Only 12% report extensive use. This mirrors findings from other institutions: at the <a href="https://drive.google.com/file/d/1ufdagea0Xm8TpiKsyvbr1Kp-kpez3z6Z/view">University of Baltimore</a>, faculty are primarily experimenting out of curiosity, and at the <a href="https://assets.pubpub.org/9evdl9pm/Liu%2520&amp;%2520Jagadish%2520(2024)_Just%2520Accepted-71708981791796.pdf">Michigan Institute for Data Science</a>, 70% of 92 faculty lack practical experience. Conversely, a <a href="https://www.nature.com/articles/s41599-023-02304-7">survey 6,311 of German students</a> shows that 63.4% have used AI tools for academic purposes.</p>

<p><img src="https://i1.wp.com/blogsmedia.lse.ac.uk/blogs.dir/9/files/2024/06/Screenshot-2024-06-04-at-16.56.22.png?resize=1506%2C450&amp;ssl=1" alt="A poll showing responses to Sage Methods lab survey question: in the past year have you used any AI powered tools or platforms to teach research methods? 57% answered no. " title="A poll showing responses to Sage Methods lab survey question: in the past year have you used any AI powered tools or platforms to teach research methods? 57% answered no. " /></p>

<p><em>Fig.1: Sage Research Methods poll.</em> </p>

<p>While students may be embracing generative AI, the majority of staff and faculty remain hesitant. For some, it’s merely a flawed search engine producing unreliable results, while for others, it’s a tool for academic dishonesty. Neither perception is particularly helpful. To navigate this complex landscape, we need better analogies to guide our understanding and use of generative AI.</p>

<blockquote>
  <p>While students may be embracing generative AI, the majority of staff and faculty remain hesitant.</p>
</blockquote>

<p>Finding these ‘use cases’ is precisely the goal of many EdTech companies. Over 100 EdTechs already incorporate generative AI models for audio, video, or text, and the past two decades have seen <a href="https://app.livestorm.co/holoniq/ai-in-higher-education-impact-and-opportunity/live?s=05b8db41-579b-4c03-b17a-50d181f73173">$22 billion invested in AI in education, with $100 million specifically for higher education tools</a>. It’s inspiring to see the innovative solutions emerging, like <a href="https://sherpalabs.co/">Sherpa Labs</a> and <a href="https://www.anywyse.audio/">Anywyse</a>, which aim to boost student engagement. However, they face the same challenge of unfamiliarity and, crucially, need to demonstrate a tangible impact on learning outcomes.</p>

<p>Early research offers mixed results. Nearly <a href="https://onlinelibrary.wiley.com/doi/abs/10.1111/jcal.12962">100 educational papers have been published on ChatGPT alone</a>, with a <a href="https://ed.stanford.edu/news/what-do-ai-chatbots-really-mean-students-and-cheating">Stanford study</a> suggesting AI chatbots haven’t increased overall cheating rates in schools. <a href="https://repository.isls.org/bitstream/1/10177/1/ICLS2023_2093-2094.pdf">Another study</a> confirms the benefits of instructors using GPT3 for positive feedback but highlights their limitations in providing constructive feedback for struggling students.</p>

<p>In courseware development, <a href="https://www.semanticscholar.org/reader/59db4a3cdb545988a2f41f68f797f2c4772d5446">Acrobatiq’s AI-generated content has shown promise</a>, but a lack of comparable historical student data makes it difficult to definitively quantify its impact. Similarly, the <a href="https://hdsr.mitpress.mit.edu/pub/xedo5giw/release/1">literature review landscape is evolving</a>, with research databases adding retrieval-augmented generation, but the effectiveness of this approach <a href="https://scholarlykitchen.sspnet.org/2024/02/21/guest-post-there-is-more-to-reliable-chatbots-than-providing-scientific-references-the-case-of-scopusai/">remains questionable</a>.</p>

<p>The potential of generative AI in education is tantalising, but current research still offers mixed results. We lack longitudinal studies, and the rapid pace of technological change renders many findings out of date. To truly understand its impact, we need <a href="https://blogs.lse.ac.uk/impactofsocialsciences/2024/05/22/to-improve-their-courses-educators-should-respond-to-how-students-actually-use-ai/">more in-classroom experiments</a>. EdTech tools are uniquely positioned to gather this crucial data, but collaboration between researchers and EdTech companies is key.</p>

<h2 id="a-silver-lining">A silver lining?</h2>

<p>Education non-profits are <a href="https://projectevident.org/wp-content/uploads/2024/02/Inspiring-Action-HAIPE-AI-report.pdf">leading AI adoption</a>, with <a href="https://www.insidehighered.com/news/quick-takes/2024/04/09/report-higher-education-most-trusted-source-handle-ai#:~:text=While%2520the%2520public%2520remains%2520cautious,business%2520intelligence%2520group%2520Morning%2520Consult.">higher education institutions gaining trust for responsible AI use</a>. Collaborative initiatives like <a href="https://www.science.org/content/article/should-researchers-use-ai-write-papers-group-aims-community-driven-standards">CANGARU</a>, <a href="https://www.princeton.edu/news/2024/03/18/ai-princeton-pushing-limits-accelerating-discovery-and-serving-humanity">institutional AI initiatives</a>, and reports from <a href="https://www.cni.org/pbs/the-arl-cni-task-force-on-ai-futures-scenarios-for-the-research-enterprise-and-research-libraries">Coalition for Networked Information &amp; Association of Research Libraries</a>, and <a href="https://ocul.on.ca/sites/default/files/20240305_OCUL-TFMLAI_InterimReport.pdf">Ontario Council of University Libraries</a> highlight proactive efforts. Ithaka S+R’s <a href="https://sr.ithaka.org/blog/making-ai-generative-for-higher-education-2/">19-university task force</a> and <a href="https://library.educause.edu/resources/2024/4/higher-education-generative-ai-readiness-assessment">EDUCAUSE’s collaboration with AWS</a> further demonstrate the sector’s commitment to understanding and responsibly integrating AI.</p>

<p>While these collaborative efforts might initially seem slower, they will ultimately speed up adoption and reduce resistance. By prioritising effectiveness and value as defined by higher education institutions themselves, they will distribute costs, leverage expertise across the sector to avoid duplication and save money. Crucially, this approach will benefit the entire sector, supporting the necessary changes to existing academic processes, such as assessments, that must evolve in response to generative AI.</p>

<p>The current enterprise AI offers like Microsoft’s Copilot or ChatGPT Edu therefore still seem to require deeper integration within core academic processes. Ultimately, the widespread adoption of generative AI in higher education hinges on the sector’s ability to demonstrate the technology’s true value and tangible efficiencies, thus making it an indispensable part of its infrastructure. Whilst we shouldn’t all sign up for the hmm crew, the future of AI in higher education is by no means decided.</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="higher education" /><category term="artificial intelligence" /><category term="software" /><category term="tools" /><category term="startups" /><summary type="html"><![CDATA[This post was originally published on the LSE Impact Blog.]]></summary></entry><entry><title type="html">Empowering research software</title><link href="https://danielagduca.github.io/tools%20&%20technology/empowering-research-software/" rel="alternate" type="text/html" title="Empowering research software" /><published>2023-04-24T00:00:00+00:00</published><updated>2023-04-24T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/empowering-research-software</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/empowering-research-software/"><![CDATA[<p>This blog was originally published in <a href="https://www.socialsciencespace.com/2023/04/empowering-research-software/">Social Science Space</a>.</p>

<blockquote>
  <h2 id="excerpt">Excerpt</h2>
  <p>The paradox of research software lies in the tension between the promotion of software as a scholarly output and the reality of software as a product that needs to be sustained beyond its publication.</p>
</blockquote>

<h2 id="using-research-software">Using Research Software</h2>

<p>The use and development of research software is integral to academic research in the social sciences and across all disciplines. In 2019, following the publication of our <a href="https://sagepublishing.github.io/sage_tools_social_science/">whitepaper on technologies for social sciences</a>, the research methods innovation group at Sage ran a survey with the community and found that close to 85 percent of social scientists were using software for research, and at least 10 percent were developing their own software. This was not surprising, considering that after a brief dive into the area, we found more than 500 software tools and technologies used across the disciplines. (Sage is the parent of Social Science Space.)</p>

<p>Research software has a broad definition and includes almost any kind of code, scripts, algorithms, and computational workflows. It is an essential component of scientific endeavors across all domains. Currently, over 90 percent of researchers use software and approximately half develop research software. One might expect then that at least 90 percent of academic papers will have cited the software that was used to collect, analyze, or manage the data and outputs, but no. Most software is mentioned in papers but rarely cited, leaving research software engineers stuck in a loop. Research software is not recognized as a scholarly output, it is hard to get credit if most papers mention the software, but few cite it, and more difficult to prove its impact and receive further funding or support. </p>

<p><a href="https://zenodo.org/record/7409765#.Y8TodexBx5x">Huge efforts have been made</a> since the development of the <a href="https://peerj.com/articles/cs-86/">Software Citation Principles</a> in 2016 to elevate software to a valuable digital object and to facilitate its reuse. Beyond an increase in the number of journals that adopted software citation policies, this work unearthed challenges around the long-term sustainability of research software.  </p>

<p>The paradox of research software lies in the tension between the promotion of software as a scholarly output and the reality of software as a product that needs to be sustained beyond its publication. We view software development as a means to an end, with funding and publication being the primary goals. However, unlike traditional research outputs, software requires ongoing maintenance and development to remain useful. This presents a significant challenge for researchers and research software engineers who want to progress in their careers, while also promoting and sharing their software It requires significant time investment to create a community that can sustain its development and ensure its longevity.  </p>

<p>Traditionally, funding has been available for the initial stages of software development, where engineers and researchers develop the prototype as an innovation. But software will go out of date if its makers have to move on to the next project. Over the last few years, several funders developed programs that focus on making software robust, scalable and reusable by bigger communities of researchers. At Sage, we have supported research software in the social sciences through our <a href="https://www.methodspace.com/concept-grants">Sage Concept Grants</a> program that has been running for five years and funded 22 software tools, prototypes and packages. </p>

<hr />
<h3 id="more-about-sage-concept-grants">More about Sage Concept Grants</h3>
<p>-
– Started in 2018 with 21 applicants, now over 100<br />
– Two types of grants: Five seed grants of £2,000 for ideas, and £15,000 for teams that have a prototype and would like to scale it<br />
– Applicants from over 40 countries, and unlike research funding organizations, Sage doesn’t have a limit on territory<br />
– Just over 40 percent applications led by women or mixed teams<br />
– Recurring themes: social media analysis, data collection and aggregation, image and video analysis, text mining, online experiments, qualitative data analysis, simulation and modelling<br />
– Most common disciplines: Research Methods, Sociology and Social Studies, Behavioural Science, Education, Computational Social Science<br />
– <a href="https://www.methodspace.com/concept-grants">Learn more and apply</a>
—</p>

<h2 id="research-software-funders-forum">Research Software Funders Forum</h2>
<p>This goal brought many of the funders together in a <a href="https://www.researchsoft.org/funders-forum/">Research Software Funders Forum</a>, an initiative coordinated by the Research Software Alliance (ReSA) and supported by Alfred P. Sloan Foundation, that Sage has also been involved with as the only academic publisher. Through this forum, funders share experiences and collaborate on best practices. Several working groups are looking into coordinating funding calls across disciplines or borders, the <a href="https://www.nature.com/articles/s41597-022-01710-x">FAIR</a> (Findable, Accessible, Interoperable and Reusable) principles for research software and how to improve evaluating software.   </p>

<p>In addition to running the Funders’ Forum, <a href="https://www.researchsoft.org/">ReSA</a> has been playing a vital role in coordinating the stakeholders to develop best practices, maintain standards and guidelines and provide resources for the community to promote the value of research software. In November 2022, ReSA and the Netherlands eScience Centre organized an international funders workshop on the <a href="https://future-of-research-software.org/">future of research software</a> where funders joined forces to explore how to further incentivize software sustainability. During the workshop, the attendees drafted a preliminary set of guidelines for the sustainability of research software and the role of funders, now referred to as <a href="https://adore.software/">The Amsterdam Declaration of Funding Research Software Sustainability</a>. The goal of the Amsterdam declaration is “to raise awareness of the role of funding practice in the sustainability of research software, and to improve that practice.” The organizers of the declaration are <a href="https://docs.google.com/forms/d/e/1FAIpQLSdWfzYm2aCElcVBBZtgDARZd3kJb7bFun8I_aek5S1JcA_Fvg/viewform">taking feedback on the declaration’s third draft</a> through May 25.</p>

<p>While significant progress has been made in elevating software as a valuable digital object and promoting its citation with the help of organizations like ReSA, the Society of Research Software Engineers, and the Software Sustainability Institute, challenges around funding and sustainability still remain. The Research Software Funders Forum and initiatives like the Amsterdam Declaration are steps in the right direction, but there is still much work to be done to improve software evaluation, promote its reuse, and incentivize its sustainability. It is only through collaborative efforts and ongoing investment in research software that we can continue to make strides in scientific research and innovation.</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="higher education" /><category term="software" /><category term="tools" /><category term="startups" /><summary type="html"><![CDATA[This blog was originally published in Social Science Space.]]></summary></entry><entry><title type="html">Why learning from digital texts is still a challenge?</title><link href="https://danielagduca.github.io/tools%20&%20technology/learning-by-reading/" rel="alternate" type="text/html" title="Why learning from digital texts is still a challenge?" /><published>2021-04-02T00:00:00+00:00</published><updated>2021-04-02T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/learning-by-reading</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/learning-by-reading/"><![CDATA[<p>Ebooks have been around <a href="https://www.theguardian.com/books/2002/jan/03/ebooks.technology">since late 70s with Project Gutenberg, and became a commercially available format as early as the internet enabled monetary exchanges in the 90s</a>. In 1998, US libraries were already distributing free ebooks through their websites and technologies from companies like OverDrive have been supporting that effort since the late 80s. Fast forward to the 2000s, Amazon and Apple brought digital to the masses with simpler ereaders and smarter phones. Yet, this move has been really slow. I mean it isn’t a Kodak moment: <a href="https://www.forbes.com/sites/ellenduffer/2019/05/28/readers-still-prefer-physical-books/?sh=4371e34c1fdf">print books are still popular</a>, and digital versions are their less-flexible equivalents.</p>

<p>We’ve temporarily enjoyed the weightlessness option: we bring all the books we want and can with us, everywhere, and we don’t carry all those backpacks with heavy textbooks that break our backs. But this isn’t enough to make us read always on our devices. Print books aren’t vintage, they are still very much a preferred option 40 years after the first books went electronic. When digital photography came about, it made it easy for anyone to become an artist, flattening the requirement to enter the field. Digital books haven’t yet delivered an impact of this scale.</p>

<p>Arguably, lower pricing and instant access are a bonus. And that helped in 2020. Tax incentives (in the UK for example) and the limitations on physical due to the pandemic boosted the digital books market, while print sales declines more than in previous years <a href="https://www.theguardian.com/books/2020/nov/14/pandemic-drives-ebook-and-audiobook-sales-by-uk-publishers-to-all-time-high-covid">with shops closed</a>. 2020 was especially catalytic for etextbooks. The working and studying from home engendered an almost prescribed growth in digital textbook sales, which is unlikely to be sustained, because learning by reading digitally continues to be a frustrating experience.</p>

<h2 id="all-you-can-read">All you can read</h2>

<p>We expect the price of digital books to be lower than print, given the absence of a physical product, which is achievable and has little impact on the underlying business model. We purchase for our Kindle or Kobo, via Hive, or even a publisher direct to consumer (D2C) subscription like that of <a href="https://www.oreilly.com/">O’Reilly</a>. We share it with family and friends, and it’s quite like what we’d do with a print book. The author can still get royalties (approximately) associated with one sale.</p>

<p>With textbooks, affordability has been a core value proposition of all the new technologies aggregating them, and they have succeeded. <a href="https://www.mckinsey.com/industries/public-and-social-sector/our-insights/the-future-of-textbooks#">Renting textbooks went mainstream in 2008</a>; according to the <a href="https://www.nacs.org/student-spending-on-course-materials-continues-to-decline">National Association of College Stores, the student spending on textbooks</a> and course materials decreased from ~$700 on average in 2008 US and Canada to ~$400 in 2020.</p>

<p>Digital library alternatives, that offer access to at least half a million books and textbooks for under $20 a month like <a href="https://www.perlego.com/">Perlego</a> (2016), and sometimes let you publish and sell your own like <a href="https://www.scribd.com/">Scribd</a> (2007), are forcing the publishing industry to rethink author royalties. While they simplify and integrate the reader’s experience, charging the price of a book or less per month, they merely replicate physical reading and have done little to transform it.</p>

<p>A similar push to disrupt the author royalty model comes from B2B digital library subscriptions, like <a href="https://bibliu.com/">BibliU</a> (2015) and <a href="https://www.kortext.com/">Kortext</a> (2013). Given the buyer is the institution, and the bundle price is driven by their size, the price per book gets into the exotic derivatives market. A library purchase can get a digital copy of the textbook that, unlike your Kindle, can be used by multiple students at the same time.</p>

<p>An intro textbook in <a href="https://opensyllabus.org/result/title?id=51539639743">Calculus</a>, for example, would be used across all STEM majors by at least half of all the first year students, so just over one thousand at a mid-size university, who can all borrow the digital copy via BibliU or Kortext. The cover price is an important incentive for the author. Writing a textbook is <a href="https://eric.ed.gov/?id=EJ1146434">a far more complex and time-consuming</a> project than a non-fiction book or any other piece of writing that academics are accustomed to doing, argues the American psychologist Robert J. Sternberg. To make an all-inclusive textbook subscription model successful, the author’s compensation must go through some form of creative destruction (assuming print is off the table), unless the price of an etextbook purchased by an institution is allowed to vary depending on an estimated number of users that will borrow it (<a href="https://www.theguardian.com/education/2021/jan/29/price-gouging-from-covid-student-ebooks-costing-up-to-500-more-than-in-print">which isn’t working very well</a> right now).</p>

<p>Digital apps from <a href="https://www.overdrive.com/">OverDrive</a> are adding to this conundrum within the book (as opposed to textbooks) library renting experience sending the idea of late fees into oblivion. The company reports that their users borrowed “<a href="https://librarytechnology.org/pr/25805">430 million ebooks, audiobooks and digital magazines in the past 12 months [2020], a 33% increase over 2019</a>”, while more than 20 thousand new libraries and schools signed up.</p>

<p>With $200M raised among them, these technologies made strides with affordability. They even tried to improve and personalize your reading experience, with functionality that ranges from changing the font and background, to highlighting the text, adding notes, text-to-speech, bookmarking, dictionaries, chapter summaries and other neat elements. These affordances replicate those of physical reading, sometimes even delighting the user with instant word searches. It works quite well when reading for pleasure; when learning, however, our brain collects information spatially. We tend to remember really well where fragments of information are located on the page and what that page looks like. We lose that ability when we read on Kortext or Perlego, and even more so with all the apps that train you to read for speed, <a href="https://www.theguardian.com/technology/2017/apr/08/speed-reading-apps-can-you-really-read-novel-in-your-lunch-hour">like Spritz and Spreeder</a>.</p>

<h2 id="second-generation-enhancements">Second generation enhancements</h2>

<p>In 2015, after 4 years of research on how college students learn with and from textbooks, a group of academics at Harvard developed <a href="https://perusall.com/">perusall</a>. Perusall isn’t addressing affordability, but rather improving the effectiveness of student reading; the application focused on the job-to-be-done: learning. And it enabled learning from book chapters, articles and other materials, through social interactivity and adding the lecturer back into the process. In other words, students can share notes and highlights, start discussions on the margin, answer each other’s questions about the material, and the instructor has all this data to help them decide when to engage.</p>

<p><a href="https://glose.com/">Glose</a> has been taking social reading to the mainstream in France and Europe since 2014; and was just <a href="https://techcrunch.com/2021/01/14/medium-acquires-social-book-reading-app-glose/">acquired by Medium</a> - the content publishing platform, an indication that social reading is already an expected feature of any reading interface. The apps fixing the affordability challenges (BibliU, Kortext, scribd, perlego, clasoos) also offer social reading functionalities. The approach to social reading that fires me up even more, in fact, is that of <a href="https://reading.supply/">reading.supply</a>. While it doesn’t contain/support books and textbooks, it does a much better job at helping you develop your knowledge while socially reading with the very neat option of manually building graphs of knowledge.</p>

<p>Independent and group notetaking while reading online is neither new nor unusual. With all the content on the internet, bookmarking and annotation evolved quite organically. <a href="https://www.diigo.com/">diigo</a> (2005), <a href="https://web.hypothes.is/">hypothes.is</a> (2011), and <a href="https://getmemex.com/">memex</a> (2015) are just a few of the tools that enable this functionality and are popular with universities. Memex builds on the idea that we learn from reading if we can build a knowledge graph, and tries to support the user in organizing the information from bookmarks and online annotation in that form. This isn’t something that I’ve seen in any of the digital textbook applications.</p>

<h2 id="can-you-read-it-all-and-learn-from-it">Can you read it all and learn from it?</h2>

<p>While notetaking has been linked with <a href="https://www.atlantis-press.com/proceedings/icat2e-17/25868789">improved learning outcomes both in print and digital</a>, there are very <a href="https://www.tandfonline.com/doi/abs/10.1080/19345747.2015.1105894?journalCode=uree20">few studies that test its benefits for college students, and even less that look at digital course text</a>. These suggest that guided notes, along with self-questioning and immediate summaries have the strongest and most consisten effect on student learning. Furthermore, we know that learning happens as a result of spaced repetition, breaking down the content, returning to previous chapters to review and flipping through the pages of later chapters to inquire.</p>

<p>These affordances are slowly being picked up by reading technologies. <a href="https://readwise.io/">Readwise</a> tried to crack spaced repetition for the kindle readers. <a href="https://www.mindstone.com">Mindstone</a> launched in February 2021 promises features that are based entirely on the science of learning. It organizes your reading and notes, compounds them into a knowledge graph, and lets you set up reminders to support spaced repetition.</p>

<p><a href="https://link.springer.com/article/10.1007%2Fs11251-007-9016-7">Retention and comprehension can also be achieved with associated visual cues</a> (like pictures and videos) in multiple media formats especially when reading in a second language. Several textbook aggregator apps are adding materials to their platforms, but that is not yet as integral a part of the main reading experience.</p>

<p><a href="https://www.goerudite.com/">Erudite</a> doesn’t yet support textbooks, but it’s transforming the reading experience for college students. Powered by several algorithms, the app breaks down the text into sections that are somewhat independent. It incorporates the ideas of highlights, note taking, spaced repetition, self-questioning and recall; all the while you are not rushing to finish reading the content, you read to internalize as much of the knowledge as you can get.</p>

<p>Most textbook products are not like Erudite or Mindstone, they focus on the distribution of the digital artefact in an affordable and all-inclusive way, rather than the job that needs to be done by the student. They are not selling the ‘learning from textbook’ experience, they exquisitely replicate the analogue at a discount, with increasingly better affordances. Yet, to deliver a product or a tool that will increase the quantity and quality of learning from textbooks will require a redefinition of the problem and a step away from the delivery of text to the delivery of a guide to learning.</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="reading" /><category term="teaching" /><category term="software" /><category term="tools" /><category term="startups" /><summary type="html"><![CDATA[Ebooks have been around since late 70s with Project Gutenberg, and became a commercially available format as early as the internet enabled monetary exchanges in the 90s. In 1998, US libraries were already distributing free ebooks through their websites and technologies from companies like OverDrive have been supporting that effort since the late 80s. Fast forward to the 2000s, Amazon and Apple brought digital to the masses with simpler ereaders and smarter phones. Yet, this move has been really slow. I mean it isn’t a Kodak moment: print books are still popular, and digital versions are their less-flexible equivalents.]]></summary></entry><entry><title type="html">Developing a comprehensive directory of tools and technologies for social science research methods</title><link href="https://danielagduca.github.io/tools%20&%20technology/tools-directory/" rel="alternate" type="text/html" title="Developing a comprehensive directory of tools and technologies for social science research methods" /><published>2021-02-11T00:00:00+00:00</published><updated>2021-02-11T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/tools-directory</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/tools-directory/"><![CDATA[<blockquote>
  <p>This post originally appeared on <a href="https://forrt.org/educators-corner/003-developing-tools/">FORRT’s Educators Corner</a></p>
</blockquote>

<p>Often the search and exploration of tools and technologies in social science research is not part of the class curriculum in the same way as the systematic review of literature is. This, sadly, leaves the becoming researcher in a place of disadvantage, in my opinion. In their early research career, students will mostly rely on their supervisor or peers to advise on the tools they use, which is still a very limited sample. However, with strides in technological development, researchers could choose from a growing number of multivariate tools for social science methods rising from within the discipline itself, as well as borrowed from other disciplines or coming from the commercial sector.</p>

<p>Starting from this premise, we decided to build a <a href="https://ocean.sagepub.com/research-tools-directory#categories">tools directory</a> for social scientists, a simple solution for a place where any researcher or student can come and find the right tool for what they need. In this piece, I explain how the tools directory was developed and how it can be used by educators, researchers and students.</p>

<h2 id="developing-the-tools-directory">Developing the tools directory</h2>

<p>The initial list was based on software tools and tech platforms that we knew were popular among social science researchers because we’ve commissioned books about them, or they have been prominent within the community. We continued to ask academics, look through papers and other lists like the <a href="http://dirtdirectory.org/">DiRT Directory</a> from the Digital Humanities, the <a href="https://wiki.digitalmethods.net/Dmi/ToolDatabase">Digital Methods Initiative</a> and <a href="https://sourceforge.net/">SourceForge</a>. Soon enough, the directory was growing out of control. What we thought would be a simple scroll down page, organised in a few basic categories, was not serving its purpose any longer.</p>

<p>With around three hundred different software packages and tools that we knew were used by some or many social science researchers in their work, a new challenge was becoming apparent. It was a paradox-of-choice situation. On one hand, it was increasingly clear why academics often rely solely on recommendations from their peers when choosing a tool. And on the other hand, we knew we needed to explore how one would choose the right tool from a list, and ultimately how to teach others to find the tool that fits their own purposes rather than simply recommending a tool they’ve used.</p>

<p>As the list grew, we enlisted the help of a few master students, and started collecting more data: who built these tools, were they free or paid, what cluster of similar tools would they belong to, when were they built, based on the information available could we tell whether they were up to date, scaling, or failed, could we find papers that cited these tools, were the creators recommending a citation etc.</p>

<p>When we hit 400 software packages/tools, we knew we had to promote this list and share it in a way that researchers would actually stumble upon it and have the opportunity to reference it in a lecture or paper. So we wrote a <a href="https://uk.sagepub.com/en-gb/eur/technologies-for-social-science-research">whitepaper summarizing the big trends on the development of tools and tech for social science research</a>. We learned that both commercial and non-commercial tools are popular within the social sciences, but the ones that last longer and are more successful focus beyond the discipline and almost always have a person or teams of people dedicated to raising funds or expanding the community of users and contributors.</p>

<p>At 400 software packages/tools, we were still not sure the list was big enough. We then focused on specific methods and researched all the tools available to carry out that method or task within the research process. We looked at the evolution of technologies for that method in particular, as well as how it fits within the development of the method itself. We call these ‘deep dives’. We’ve done deep dives on tools for annotation, or tools for transcription, surveying tools, tools for studying social media data, and we kept finding more software applications within each of these areas. We concluded these deep dives to be quite useful, as they enabled sharing slightly more comprehensive sub-lists of tools that could be used in different modules. We have now 543 tools on the list, and the number keeps growing.</p>

<h2 id="how-to-use-the-tools-directory">How to use the tools directory</h2>

<p>The full directory is currently available on our <a href="https://sagepublishing.github.io/sage_tools_social_science/">GitHub repository</a> as a csv file. We decided to host it on GitHub, in order to be able to update the directory when we come across new tools or after deep dives; ensure it’s always available for others to reuse in its most up-to-date form, and enable instructors, students and researchers to add tools that might be missing.</p>

<p>Educators teaching research methods or preparatory courses for students’ theses could present the full tools directory to students, so they are more flexible in finding the right tools for their needs and future projects.Students can browse through the list and filter for tools to find a tool that is most appropriate for a research project they are initiating. For example, a student transcribing interviews might look at the transcription tools to find alternatives. Similarly, educators that are teaching a more specialized course, such as introduction to text mining, data visualization, or social data mining, or running online experiments could filter out a sub-list of tools focusing on the explicit method. They could then share this sub-list as part of the course reference materials or assignments.</p>

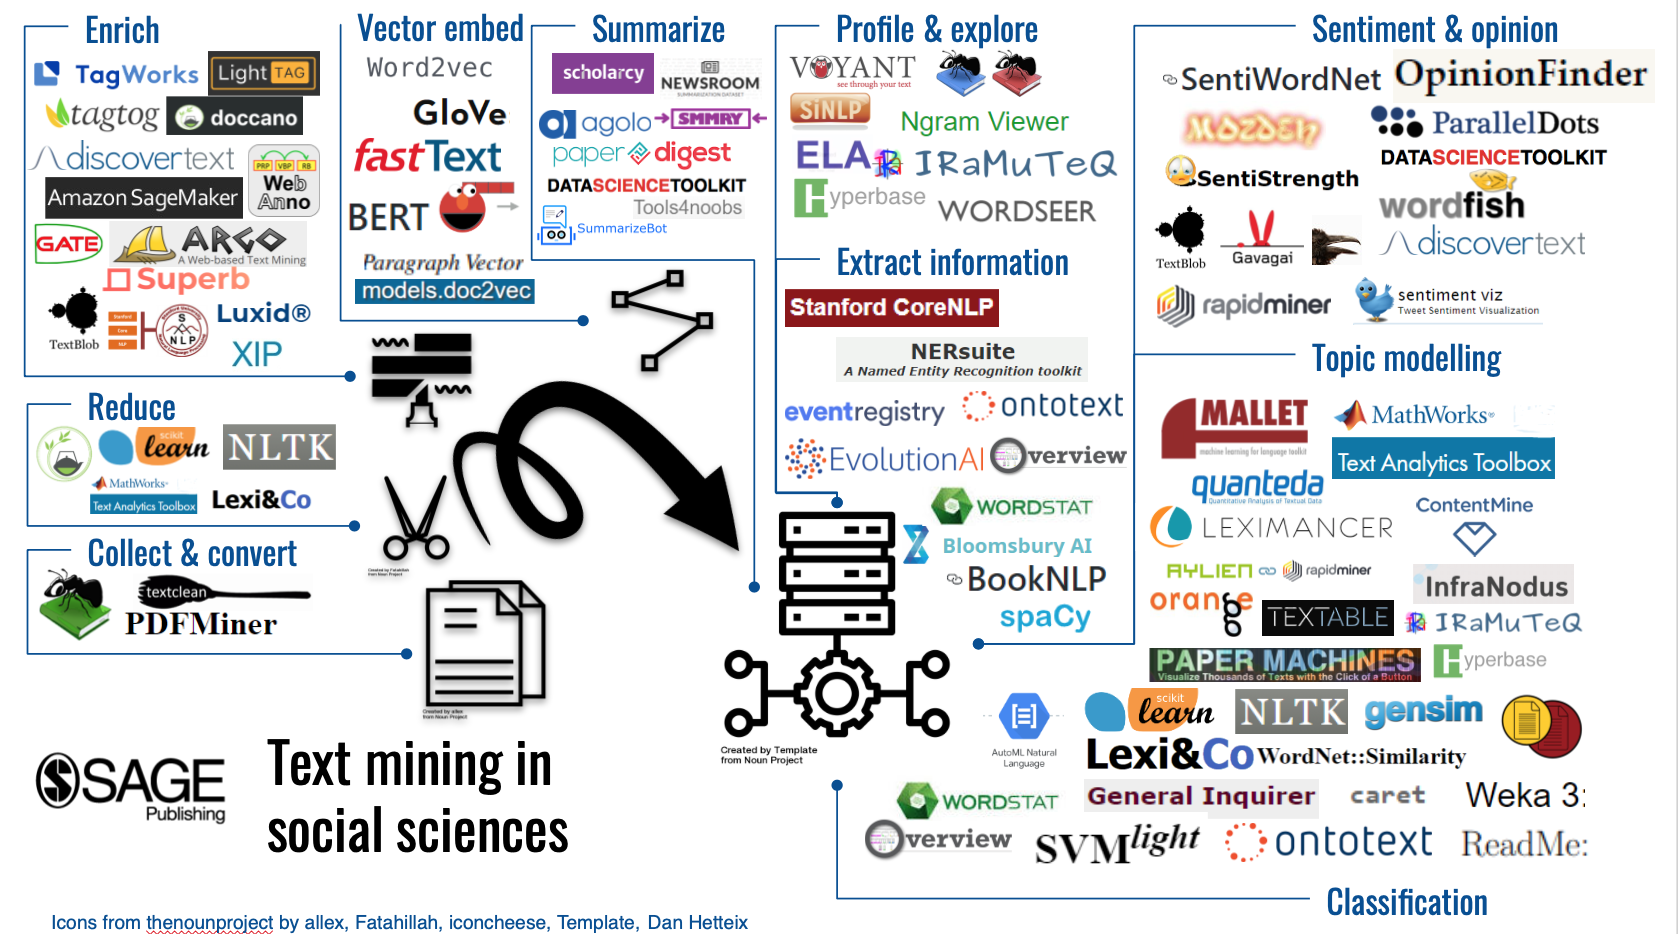
<p><img src="https://forrt.org/educators-corner/003-developing-tools/featured.png" alt="Fig. 1. The spread of 543 tools and technologies across methods and techniques." title="Fig. 1. The spread of 543 tools and technologies across methods and techniques." /></p>

<p>Fig. 1. The spread of 543 tools and technologies across methods and techniques.</p>

<p><img src="https://forrt.org/educators-corner/003-developing-tools/fig2.png" alt="Fig. 2. Filtering to find transcription tools. A student or instructor could filter by column F (the Competitive cluster which contains the method/technique/task/area that we used to categorize the tool) to get a sub-list of tools that could be broadly used for a particular process. If the cluster is too broad, the student can look through the technique (column E), that breaks it down further. For example for social media tools, the technique would include analysis, collection, visualisation etc. If looking for more recent tools, one can filter by the year the tool was launched (column M); or if the student is interested in something that is free, they can check the charges (column N)." title="Fig. 2. The spread of 543 tools and technologies across methods and techniques." /></p>

<p>Fig. 2. Filtering to find transcription tools. A student or instructor could filter by column F (the Competitive cluster which contains the method/technique/task/area that we used to categorize the tool) to get a sub-list of tools that could be broadly used for a particular process. If the cluster is too broad, the student can look through the technique (column E), that breaks it down further. For example for social media tools, the technique would include analysis, collection, visualisation etc. If looking for more recent tools, one can filter by the year the tool was launched (column M); or if the student is interested in something that is free, they can check the charges (column N).</p>

<p>While the csv file that contains the tools directory might be easy to update and share, we acknowledge that it might not be that easy to use within a classroom. We are experimenting with a variety of ways that would enable a better display and navigation of the directory, without losing from the ease of updating it.</p>

<p>In 2019 we did our first deep dive into the tools for social data science to support our <a href="https://campus.sagepub.com/collecting-social-media-data">SAGE Campus course on collecting social media data</a>. We created a sublist to share for this course to help learners find the software that might be most appropriate for their own project, especially given the variety of social media platforms available. To render <a href="https://airtable.com/shrux4hYwNG1cOyjK/tbl9NiGq87agePZ2M?backgroundColor=cyan&amp;viewControls=on">the sub-list</a> in a more friendly way, we used the free version of airtable, which is a no-code app for relational databases with a colorful and modern interface. Students would navigate to this page (Fig 3) to see the sub-list on a single table. They can then find the right tool for their social media project by selecting the platform they want to collect their data from (twitter, instagram, facebook etc), whether they are happy to pay or looking for something that’s free, and the type of task they want to perform: whether they need the tool for collecting the data, analysis, or visualization. Once they have a filtered list, they can also look through the academic papers we’ve linked where each tool has been used, to explore further the potential of the tools.</p>

<p><img src="https://forrt.org/educators-corner/003-developing-tools/fig3.png" alt="Fig. 3. Screenshot of the sub-list containing social media tools via the free version of airtable. Similar to working with a csv file (as in Fig. 2), this interface lets the student filter the list down to narrow the choices for a tool they could use to either collect or analyse their data. This interface is web-based, and has a more inviting user experience than working with a csv file. A student can easily see the categories of tools, filter by multiple terms or concepts linked within each of the columns." title="Fig. 3. Screenshot of the sub-list containing social media tools via the free version of airtable. Similar to working with a csv file (as in Fig. 2), this interface lets the student filter the list down to narrow the choices for a tool they could use to either collect or analyse their data. This interface is web-based, and has a more inviting user experience than working with a csv file. A student can easily see the categories of tools, filter by multiple terms or concepts linked within each of the columns." /></p>

<p>Fig. 3. Screenshot of the sub-list containing social media tools via the free version of airtable. Similar to working with a csv file (as in Fig. 2), this interface lets the student filter the list down to narrow the choices for a tool they could use to either collect or analyse their data. This interface is web-based, and has a more inviting user experience than working with a csv file. A student can easily see the categories of tools, filter by multiple terms or concepts linked within each of the columns.</p>

<p>We envision this sub-list of social media tools to be a starting point, as it helps the learner filter down based on a limited number of criteria, such as: the task that can be achieved (collection, analysis), the social media platform that’s integrated, and the fees.</p>

<p>We’ve reused the same <a href="https://socialmediatools.pory.app/">sub-list of social media tools with a different interface</a> (pory.io, currently in beta) to render this list of tools more akin to a catalogue of records, that the student can search and filter. This rendering was used in a bootcamp on starting off with social media research. Similar to the airtable rendering, a student could filter based on the task they want to achieve and then click into the tool to get more information and explore which one would work better.</p>

<p><img src="https://forrt.org/educators-corner/003-developing-tools/fig4.png" alt="Fig. 4: Screenshot of the sub-list of social media tools rendered into a catalogue via the pory.io app. The user experience on this interface is friendlier than working with a table as in Fig. 2 &amp; 3. A student can filter the list by the type of tool, which is immediately visible; for example they might be looking for tools to support their data collection. They can then use the search box to enter key terms and narrow down the list further, a process that is more familiar. The student can also browse the list of tools by opening the individual cards to find more information (see next figure)." title="Fig. 4: Screenshot of the [sub-list of social media tools](https://socialmediatools.pory.app/) rendered into a catalogue via the pory.io app. The user experience on this interface is friendlier than working with a table as in Fig. 2 &amp; 3. A student can filter the list by the type of tool, which is immediately visible; for example they might be looking for tools to support their data collection. They can then use the search box to enter key terms and narrow down the list further, a process that is more familiar. The student can also browse the list of tools by opening the individual cards to find more information (see next figure)." /></p>

<p>Fig. 4: Screenshot of the <a href="https://socialmediatools.pory.app/">sub-list of social media tools</a> rendered into a catalogue via the pory.io app. The user experience on this interface is friendlier than working with a table as in Fig. 2 &amp; 3. A student can filter the list by the type of tool, which is immediately visible; for example they might be looking for tools to support their data collection. They can then use the search box to enter key terms and narrow down the list further, a process that is more familiar. The student can also browse the list of tools by opening the individual cards to find more information (see next figure).</p>

<p><img src="https://forrt.org/educators-corner/003-developing-tools/fig5.png" alt="Fig. 5. Fig. 5: Once the student filters a list of tools, they can click one each card to get further information about each tool. Currently this includes a brief description, the platform supported, whether it’s free or not, and several academic papers that have used this tool." title="Fig. 5: Once the student filters a list of tools, they can click one each card to get further information about each tool. Currently this includes a brief description, the platform supported, whether it’s free or not, and several academic papers that have used this tool." /></p>

<p>Fig. 5: Once the student filters a list of tools, they can click one each card to get further information about each tool. Currently this includes a brief description, the platform supported, whether it’s free or not, and several academic papers that have used this tool.</p>

<p>Airtable and pory.io have different affordances for rendering the sub-lists of tools, and our experience so far is that both have been useful. We are hoping to learn more from these experiments, to understand the student’s journey as well as the data that would inform their exploration process.</p>

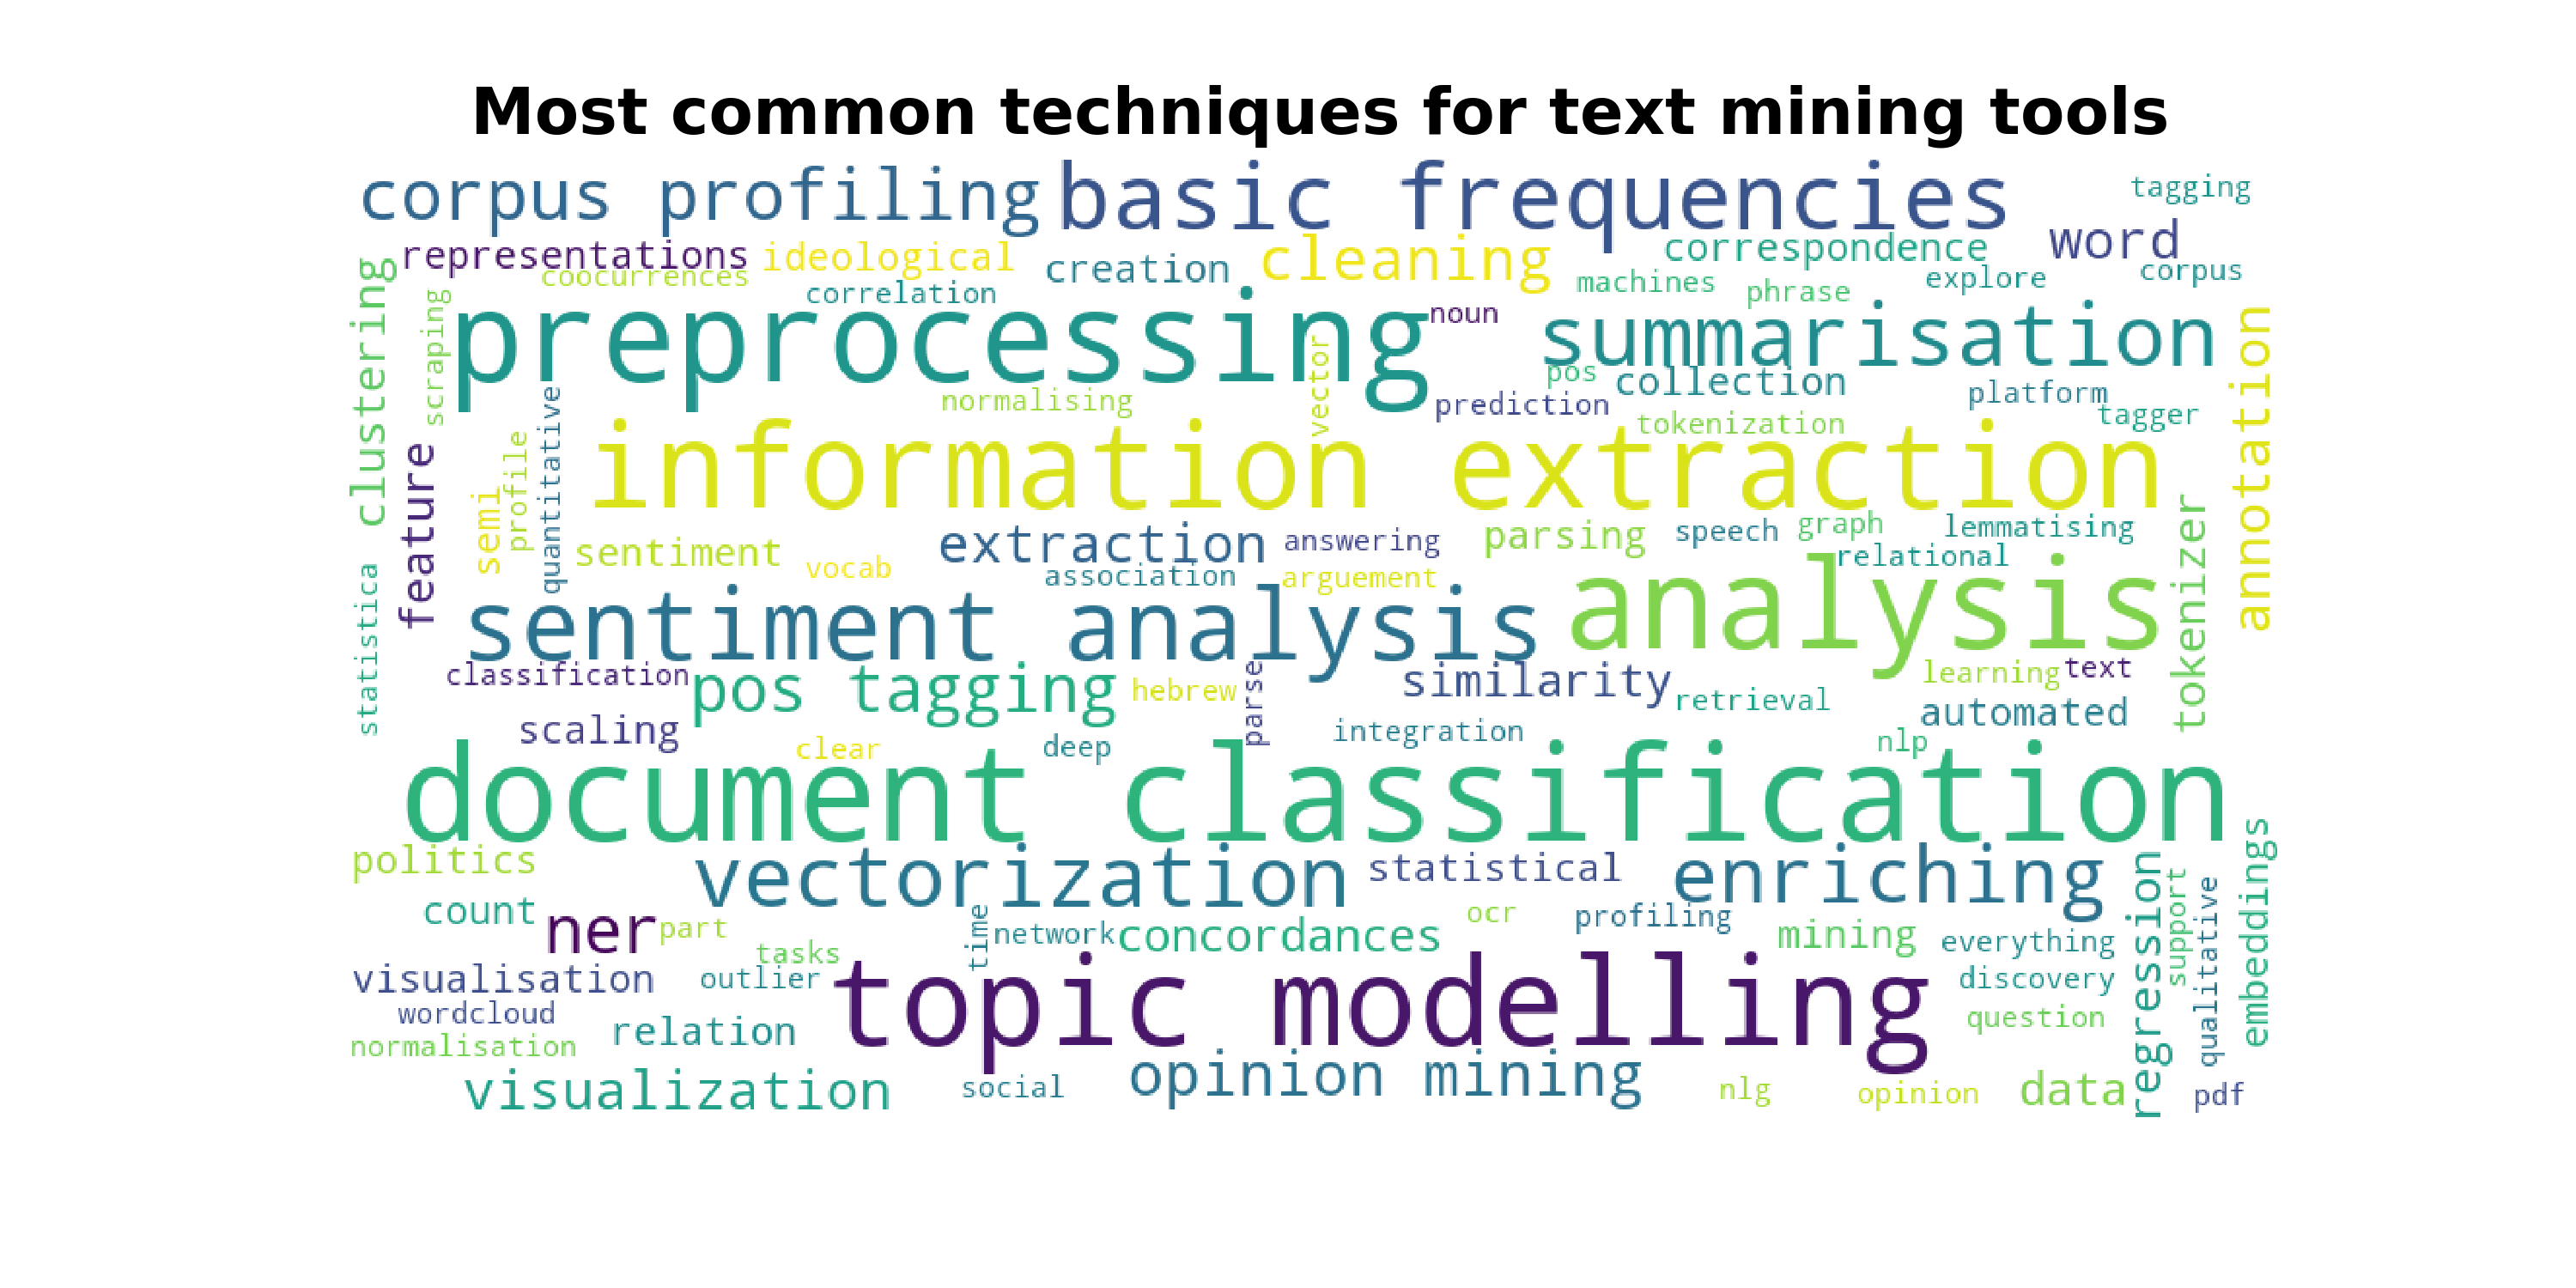
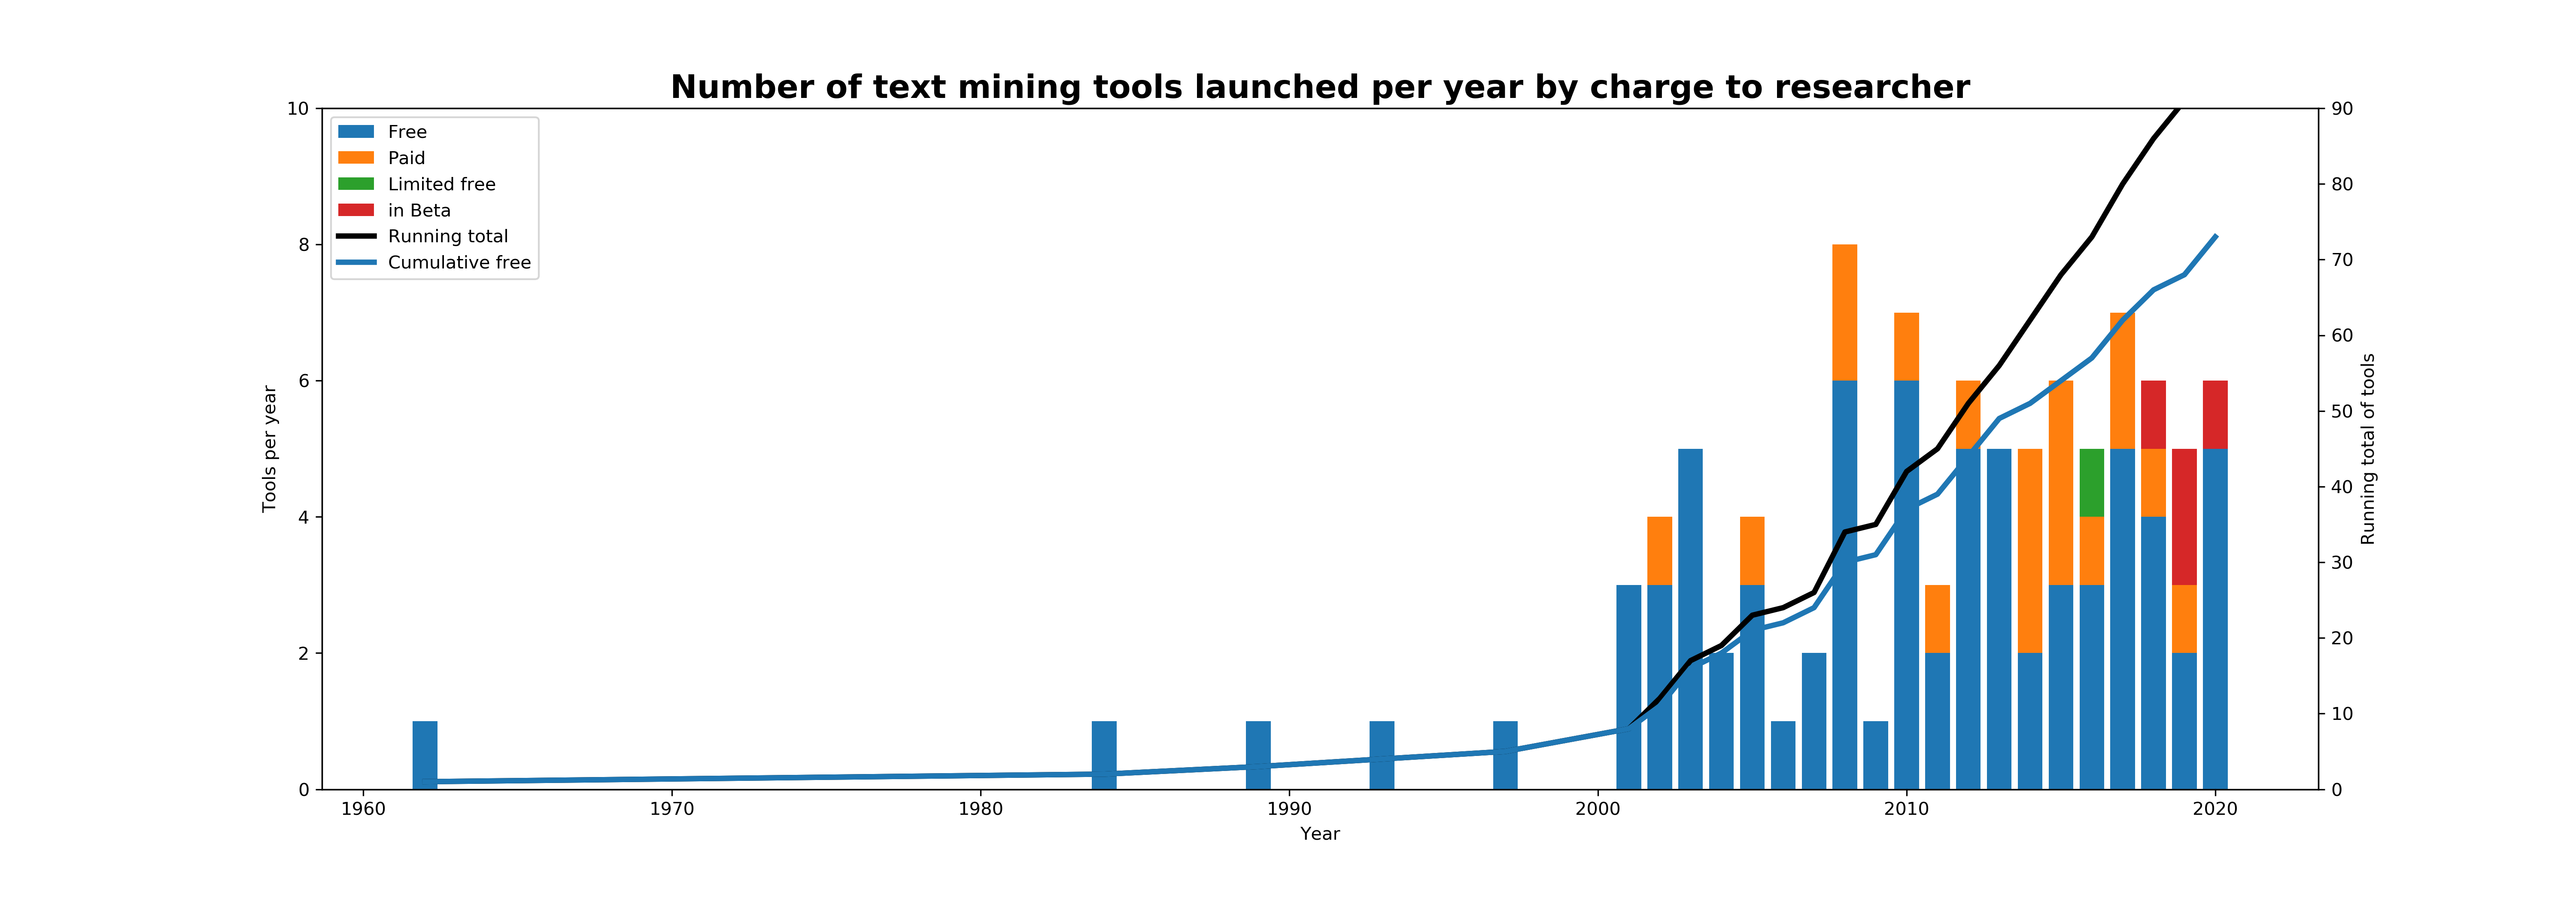
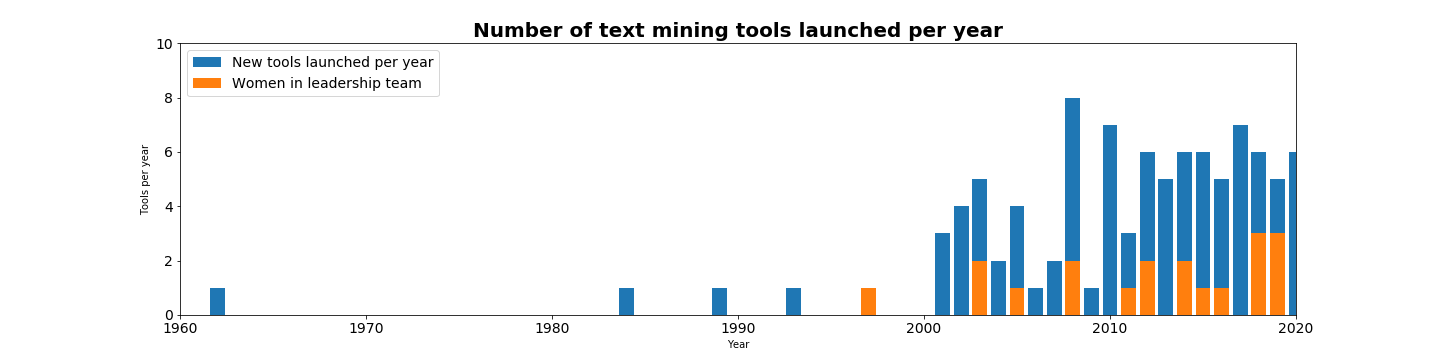
<p>The social media tools sub-list was part of a deep dive that we carried out in 2019. Since then, we dived into <a href="https://sagepublishing.github.io/sage_tools_social_science/2019/11/11/surveying-tools.html">surveying tools</a> and <a href="https://sagepublishing.github.io/sage_tools_social_science/2020/01/20/text-mining.html">text mining</a>. We have not created separate sub-lists for these, and encourage instructors to try other ways of representing these tools within their courses. If you are teaching text mining in the social sciences, for example, you can point your students to this <a href="https://sagepublishing.github.io/sage_tools_social_science/2020/01/20/text-mining.html">overview of the text mining tools available</a> (Fig. 6 &amp; Fig. 7) and share a sub-list of the tools directory filtered for text mining with your students.</p>

<p><img src="https://forrt.org/educators-corner/003-developing-tools/fig6.png" alt="Fig. 6: Screenshot of the Text Mining section, an overview of tools available." title="Fig. 6: Screenshot of the Text Mining section, an overview of tools available." /></p>

<p>Fig. 6: Screenshot of the Text Mining section, an overview of tools available.</p>

<p><img src="https://forrt.org/educators-corner/003-developing-tools/fig7.png" alt="Fig. 7: Text mining tools and technologies based on the process they support." title="Fig. 7: Text mining tools and technologies based on the process they support." /></p>

<p>Fig. 7: Text mining tools and technologies based on the process they support.</p>

<h2 id="going-forward">Going forward</h2>

<p>Going forward, we are quite interested in finding out what are the criteria people often use to filter down to their top tools, so we can build this list forward and continuously add the data that helps academics and students find the tools that fit their project best.</p>

<p>We understand that lists follow some form of a hype cycle, where there is a lot of work done at the start and some engagement from the community, and then the whole project slowly dies and it is forgotten. It becomes pretty unusable, because with the pace of research and technology, a lot of the tools are out of date and many new ones have popped up. A person must be dedicated to updating the list and for now we have that covered. Since the publication of the whitepaper in November 2019, we’ve added at least 100 more tools, mostly focusing on text and data mining. While it’s relatively easy to come across new tools, the hardest bit is updating the ones that are already on the list, and that’s where we are open for suggestions from the community. The list with updates to the whitepaper are available in this <a href="https://sagepublishing.github.io/sage_tools_social_science/">GitHub repository</a>.</p>

<p>Finally, the <em>locus</em> of software tools and technologies within the research ecosystem remains a big challenge. Software tools are yet to gain the credit of research output. And that is why, among other reasons, software tools are rarely cited or referenced in papers. This is not only bad for <a href="https://www.slideshare.net/danielskatz/citation-and-reproducibility-in-software">reproducibility of research, but it also makes it difficult to help other researchers weigh in and compare different tools</a> used for similar studies. We aim to promote and include the suggested citation of the tools in our list, and strongly encourage anyone to use <a href="https://citeas.org/">https://citeas.org</a> when unsure how to give credit to these.</p>

<p>We remain active and are continuously thinking of better ways to present and re-architecture the information about software tools and technologies we’ve gathered, to make it easier to navigate and explore. We hope these materials will help you and your students become more aware of the diversity of tools and technologies and will open new and potentially easier avenues to decide on the best software tool to use for your research.</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="social science" /><category term="teaching" /><category term="software" /><category term="tools" /><category term="startups" /><summary type="html"><![CDATA[This post originally appeared on FORRT’s Educators Corner]]></summary></entry><entry><title type="html">The challenges of running social science experiments from home - and 14 tools that can help</title><link href="https://danielagduca.github.io/tools%20&%20technology/experiments-tools/" rel="alternate" type="text/html" title="The challenges of running social science experiments from home - and 14 tools that can help" /><published>2020-12-10T00:00:00+00:00</published><updated>2020-12-10T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/experiments-tools</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/experiments-tools/"><![CDATA[<blockquote>
  <p>This post originally appeared on <a href="https://ocean.sagepub.com/blog/">SAGE Ocean</a></p>
</blockquote>

<p>Never have the social and behavioral sciences been as critical as they have been during the COVID-19 pandemic and associated lockdown. More data was on demand and it was demanded instantly, along with the most robust analysis and policy recommendations, which meant that the classic research methods needed some creativity to transition to a socially distanced world. Data collection methods have been adapting not just to answer pressing questions about the <a href="http://blog.ukdataservice.ac.uk/covid-19-social-surveys/">impact of COVID</a> on <a href="https://digest.bps.org.uk/2020/03/26/how-psychology-researchers-are-responding-to-the-covid-19-pandemic/">individuals</a> and society, but also <a href="https://www.frontiersin.org/articles/10.3389/fpsyg.2020.01786/full">accelerating the ways in which they could be carried out digitally</a>.</p>

<p>Digital methods are not new to the social sciences: surveys have gone digital since the 90s, with the recent Mechanical Turk, Prolific, Call for Participants and even social media marketing enhancing the digital recruiting of participants. The increase in the use of social media to cover 3.6B of the world’s population has allowed academics both to use the data from these platforms for research, as well as augment the sample snowballing methods. In the more recent years, trends around misinformation and fake news online have triggered teams of academics to develop online games such as <a href="https://www.getbadnews.com/#intro">GetBadNews</a> and <a href="https://hoaxy.iuni.iu.edu/">Hoaxy</a> that teach the average internet user about misinformation, and also function as a way to test theories of learning and retention.</p>

<p>A growing number of social science researchers are shifting to digital methods, but it’s not an easy task, and this has been even more evident in lockdown. Some research methods are challenging (or even impossible) to run digitally, for example, experiments that can only be done in person or research that focuses on <a href="https://ourworldindata.org/internet">groups or regions that are hardly online</a>. Even the fully digital VR experiments that we wrote about in another <a href="https://ocean.sagepub.com/blog/virtual-reality-the-future-of-experimental-social-research">blog</a> are difficult when the hardware is not available or can only be accessed in a lab. So what can you do if you want to continue doing social science experiments and scale them up while working from home?</p>

<p>We’ve selected 14 software tools that you can start using immediately to run your social or behavioral experiments online. Some come with integrated recruitment, others leave that bit to you; some are for asynchronous experiments, others let you run your experiment with multiple users at the same time; some work for small groups, others for thousands or more. As a bonus, and for those of you who want to go fully digital and forget about recruiting, we’ve included two bonus tools you can use to design and run simulated or computational experiments.</p>

<p>We spoke to some of these tools’ creators about what they think are the biggest challenges of running experiments remotely. Read their answers here or <a href="https://ocean.sagepub.com/blog/tools-and-technology/challenges-of-running-social-science-experiments-from-home-and-14-tools-to-help#softwaretools">jump straight to the list of tools</a>.</p>

<h3 id="claudia-von-bastian-of-tatool">Claudia von Bastian of <a href="http://www.tatool.ch/">Tatool</a></h3>

<p>The main challenges of conducting experiments remotely are <strong>portability</strong> (running experiments across platforms, browsers, and devices, <strong>usability</strong> (creating unambiguous instructions to ensure that participants are actually doing what you want them to do, and <strong>quality</strong> (having checks in place to determine whether the data quality of participant-generated data sets).</p>

<h3 id="chris-wickens-of-otree">Chris Wickens of <a href="https://www.otree.org/">oTree</a></h3>

<p>I think a big challenge of running online multiplayer experiments is <strong>dropouts</strong>. In a lab you can ensure that people play at the same time and that they all complete the experiment. Online this is much harder. With a multiplayer experiment, there is the risk that some participants will be stuck waiting for someone who dropped out (or lost their internet connection, etc).</p>

<h3 id="ting-qian-of-finding-five">Ting Qian of <a href="https://www.findingfive.com/">Finding Five</a></h3>

<p>We are hearing from researchers that the biggest challenge in shifting to online experiments has been the <strong>lack of time and technical resources</strong> for (re)creating their experiments online. Further, since researchers can no longer invite participants to the lab and have them complete the task on a standardized lab computer, another concern is accounting for <strong>variability</strong> across participants’ devices. For instance, without adequate corrections, mouse tracking results can look vastly different when participants use a mouse as opposed to a laptop trackpad.</p>

<h3 id="jo-evershed-of-gorilla">Jo Evershed of <a href="https://gorilla.sc/">Gorilla</a></h3>

<p>One concern for people new to online research is <strong>maintaining data quality</strong> when conducting online experiments. Thankfully, once you unpack all the different elements that can impact data quality, it’s not that much different to maintaining data quality in the lab. Dr Jenni Rodd gave an excellent lecture on this at our BeOnline2020 conference, the video can be viewed <a href="https://gorilla.sc/support/blog/data-jenni-rodd">here</a>.</p>

<h3 id="jason-radford-of-volunteer-science">Jason Radford of <a href="https://volunteerscience.com/">Volunteer Science</a></h3>

<p>There are two big challenges to running online experiments: <strong>Choosing the right software</strong> and <strong>recruiting subjects</strong>. Different fields have different experimental traditions, so if you’re working across multiple areas then it can be hard to find the right software. When it comes to recruiting subjects, the issue is usually a lack of funding, or having to figure out where to find volunteers. It’s for these reasons that we designed Volunteer Science to be discipline agnostic, and to give you the choice of building your own participant pool, syncing with Mechanical Turk, or tapping into our existing pool of tens of thousands of volunteers.</p>

<p><a href="http://pebl.sourceforge.net/"><strong>PEBL</strong></a> is a free software specifically designed for use in psychology. It lets you design your own experiments or use any of the ready-made ones. It’s also a great tool to use in your teaching, since you can build and exchange experiments freely.</p>

<p><a href="http://www.tatool.ch/"><strong>Tatool</strong></a> is an open-source easy to use tool for experts, as well as newbies. You can either download the software, or use the web version. You’d have to recruit your own participants, but they can access the tool from anywhere and any browser. It also has the option of running your experiments offline, but you’d probably need to be in a lab for that?</p>

<p><a href="http://www.expfactory.org/about"><strong>Experiment Factory</strong></a> is another open source tool that offers a collection of experiments and the ability to integrate the recruitment with Mechanical Turk. It’s still in beta, but you can sign up or reach out to the team behind it at the <a href="http://poldracklab.stanford.edu/"></a> <a href="http://poldracklab.stanford.edu/">Poldrack Lab</a>, Stanford University.</p>

<p><a href="https://gorilla.sc/"><strong>Gorilla</strong></a> is one of the more well-known commercial solutions for designing and running online experiments in behavioral sciences, integrates participant recruitment. Gorilla is great for research and for teaching!</p>

<p><a href="https://pstnet.com/products/e-prime/"><strong>E-Prime</strong></a> is a relatively comprehensive software for behavioral research. The company has some pretty sweet hardware tools and sensors as well, but you’d probably need to meet the person face to face and set them up.</p>

<p><a href="https://www.otree.org/"><strong>OTree</strong></a> is an open source platform that is commonly used to design experiments in economics among other disciplines, with the ability to run multi-player strategy experiments. OTree also integrates with Mechanical Turk.</p>

<p><a href="https://lioness-lab.org/"><strong>Lioness</strong></a> is a free web-based platform for designing and running your experiments that is super popular in economics as well. The team behind it works really hard to enable researchers to run experiments with simultaneous participants that are incentivized to hold their attention and not drop out!</p>

<p><a href="https://www.psytoolkit.org/"><strong>PsyToolKit</strong></a> is a free-to-use toolkit for demonstrating, programming, and running cognitive-psychological experiments and surveys, including personality tests. It’s great for doing research and for teaching.</p>

<p><a href="https://www.findingfive.com/"><strong>FindingFive</strong></a> is one of the newer tools for running your experiments online. It has some pretty cool features like blocking anyone who is trying to do the experiment again, and makes it easy to set up any exclusion criteria or prerequisites when you recruit your participants via Mechanical Turk.</p>

<p><a href="https://lab.js.org/"><strong>Lab.js</strong></a> is also among the newer players in this space. It’s free and open source, you don’t need any coding skills, and has great resources for starting off doing an experiment or teaching about it.</p>

<p><a href="https://nodegame.org/"><strong>nodeGame</strong></a> has a variety of features. It’s web-based, works on mobile too. It’s free and can scale to thousands of users participating in the experiment at the same time, but also lets you replace humans with simulated bots. I’d say pretty sweet!</p>

<p><a href="http://empirica.ly/"><strong>Empirica</strong></a> is an open source tool, quite similar to nodeGame as both are developed in JavaScript, and lets you scale your experiments to thousands of users interacting simultaneously. Their mission is to help researchers easily iterate on sophisticated experimental designs.</p>

<p><a href="https://volunteerscience.com/"><strong>Volunteer Science</strong></a> is an online experiments tool that enables researchers to run live and longitudinal experiments, with simultaneous or asynchronous participants. It’s excellent to use in the lab, from home or in the classroom. Read Jason’s recommendations on <a href="https://ocean.sagepub.com/blog/collecting-social-media-data-for-research">how to recruit your participants</a> in a pandemic.</p>

<p><a href="http://breadboard.yale.edu/"><strong>Breadboard</strong></a> is a software platform developed by a group of researchers at Yale that supports researchers in designing and running experiments with participants on networks. The platform also supports the recruitment.</p>

<h2 id="bonus-tools-for-computational-experiments">Bonus: Tools for computational experiments</h2>

<p><a href="http://www.wings-workflows.org/"><strong>Wings</strong></a> is a semantic workflow system that assists scientists with the design of computational experiments.</p>

<p><a href="https://codalab.org/"><strong>CodaLab</strong></a> is an ecosystem for conducting computational research in a more efficient, reproducible, and collaborative manner. There are two aspects of CodaLab: worksheets and competitions. Worksheets lets you design and run your machine learning experiments in the cloud, plus, you can follow by publishing the experiment in a markdown file or executable paper. The competitions section is for hosting and participating in competitions in various areas requiring some computational tools and experiments.</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="online experiments" /><category term="epxperimental research" /><category term="social science" /><category term="computational social science" /><summary type="html"><![CDATA[This post originally appeared on SAGE Ocean]]></summary></entry><entry><title type="html">Unbundling the remote quantitative methods academic: Coolest tools to support your teaching</title><link href="https://danielagduca.github.io/tools%20&%20technology/unbundling-teaching/" rel="alternate" type="text/html" title="Unbundling the remote quantitative methods academic: Coolest tools to support your teaching" /><published>2020-12-07T00:00:00+00:00</published><updated>2020-12-07T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/unbundling-teaching</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/unbundling-teaching/"><![CDATA[<blockquote>
  <p>This post originally appeared on <a href="https://ocean.sagepub.com/blog/">SAGE Ocean</a></p>
</blockquote>

<p>This year’s lockdown challenged the absolute core of higher education and accelerated or <a href="https://er.educause.edu/articles/2020/3/the-difference-between-emergency-remote-teaching-and-online-learning">rather imposed the adoption of digital tooling</a> to fully replace the interactivity of the physical classroom. And while other industries might have suffered losses, the edtech space flourished, with <a href="https://news.crunchbase.com/news/back-to-school-edtech-vc-funding-reaches-4-1b-so-far-this-year/">funding for edtech almost doubling in the first half of 2020 vs 2019</a>. Even before the pandemic, lecturers were starting to feel overwhelmed by the amount of choice to support their teaching. More funding just meant more hype, more tools, and more tools working on similar or slightly improved solutions, making it even harder and more time-consuming to find and adapt them in a rush.</p>

<p>Below, I take a look at several tools and startups that are already supporting many of you in teaching quantitative research methods; and some cool new tools you could use to enhance your classroom.</p>

<h2 id="adding-interactivity">Adding interactivity</h2>

<p>A challenge when teaching remotely is to ask the class to raise their hand, or shout out words and phrases. Perhaps you use a whiteboard to explain different concepts or want to involve the class in an idea generation process. All these are possible with the tools in this category when you are comfortably sitting in your living room. Although, you still might not be able to gauge the mood or see some sparkles in the eyes of your students, as you can when teaching in an auditorium.</p>

<p><a href="https://www.mentimeter.com/">Mentimeter</a> offers a simple way to run polls, ask questions with multiple-choice, or word entries; you can show the results live.</p>

<p><a href="https://ideaboardz.com/">IdeaBoardz</a> and <a href="https://en.linoit.com/">Lino</a> are both web apps for ideation and for collaboratively writing sticky notes, so for the more hands-on activities.</p>

<p><a href="https://canvas.apps.chrome/">Canvas from Chrome</a>, <a href="https://jamboard.google.com/">Jamboard from Google</a>, and <a href="https://awwapp.com/">Aww</a> are web-based whiteboards; all three quite basic and collaborative, with some differing functionality, like slides and sticky notes on Jamboard.</p>

<h2 id="tools-to-create-better-video-and-other-types-of-content">Tools to create better video and other types of content</h2>

<p>You are probably using Zoom, Google Meet, MS Teams, or another conferencing tool to deliver or record your lecture. They all have different features and bar some security issues, Zoom has been definitely the favorite. If you were looking for something to #FixTheInternet, check out <a href="https://us.meething.space/">Meething</a> from the Mozilla Builders Incubator.</p>

<p>With <a href="https://go.playposit.com/">PlayPosit</a> and <a href="https://edpuzzle.com/">EdPuzzle</a>, you can add quizzes and notes inside your video recording for asynchronous learning.</p>

<p>The coolest app to come out this year from the co-founders of <a href="https://www.coursera.org/">Coursera</a> is a complete rebuild of the live and remote video lecture called <a href="https://www.engageli.com/">engageli</a>. The app comes with engagement stats and other embedded functionality that helps you monitor your entire session when body language and drowsing eyes aren’t there to gauge.</p>

<p>If you are thinking about accessibility and different modes of learning, there is something to help here as well. <a href="https://www.avid.fm/">Avid.fm</a> and <a href="https://www.alpeaudio.com/">Alpe</a> are already working with several academics to develop audio courseware solutions. And if you are feeling inspired, try <a href="https://gosynth.com/">GoSynth</a> to create four-minute audio snippet explainers into your course materials.</p>

<p>For those that had some VR experience before the lockdowns, and have a relatively small class with students that own headsets, do explore <a href="https://www.wondavr.com/">WondaVR</a>, you can easily use it to create some very exciting and alternative content.</p>

<h2 id="enhancing-the-learning-experience-for-your-students">Enhancing the learning experience for your students</h2>

<p>Now I know what you might say, updating or changing the LMS you are using is a gargantuan type of a task and not within your remit. But if you do have the time AND the idea of enhancing your students learning experience through classroom discussions (now online) sounds like your cup of tea, then have a look at these amazing tools.</p>

<p><a href="https://parlayideas.com/">Parlay</a> and <a href="https://www.packback.co/">PackBack</a> are exclusively solving the challenge of classroom discussions gone digital. <a href="https://aula.education/">Aula</a> and <a href="https://www.eduflow.com/">eduflow</a> are adding that on top of their slick LMS functionality. <a href="https://app.peerscholar.com/">PeerScholar</a> goes one step further and includes peer-to-peer reviews for iterations on classroom assignments and before these go to be graded by you, the instructor. <a href="https://www.kritik.io/">Kritik</a> adds team-based learning capabilities.</p>

<h2 id="tools-for-running-labs">Tools for running labs</h2>

<p>While the other categories of tooling I discussed so far are useful across many disciplines, teaching labs or how to use statistical tools and programming are unique to the social sciences and are the most challenging aspect to carry out online. When physically in the same room, you walk through the rows of students and can quickly pick up if any of them are stuck but aren’t saying anything. At that point, you or your teaching assistants jump in and help without disturbing the rest of the class.</p>

<p>I wish I could share some tools that can help with that challenge, but alas, I found nothing yet.</p>

<p>There are, however, some ways you can make the lab experience a bit easier both for you and your students. Leaving the practical tips for another blog, right now you could try <a href="https://observablehq.com/">Observable</a> — it’s a web-based collaborative notebook to build dashboards and run ad-hoc and visual data explorations. If that’s intimidating and you are mostly using R and excel spreadsheets with modest datasets, check out <a href="https://www.jamovi.org/">jamovi</a>, a user-friendlier way to do stats, open-source.</p>

<p>For the student that’s always in search of the newest tools and the edge cases, or one more trending language to learn, guide them towards <a href="https://juliahub.com/docs/Pluto/OJqMt/0.7.4/">Pluto.jl</a>, a notebook for Julia.</p>

<p>Finally, when teaching how to set up and run online experiments, <a href="https://volunteerscience.com/">Volunteer Science</a> and <a href="https://lab.js.org/">lab.js</a> are among some of the tools that render that ordeal into quite a smooth experience. If you want to delve further in into this space <a href="https://ocean.sagepub.com/blog/tools-and-tech/moving-your-behavioral-research-online">we’ve written more about tools for online experiments earlier in the year</a>.</p>

<h2 id="more-resources">More resources</h2>

<p><a href="https://www.panopen.com/">PanOpen</a> is a courseware solution for open education resources, and you can also find relevant materials on <a href="https://www.oercommons.org/">OER Commons</a>. If you are not up for searching or adopting a new tool and are just looking for materials from other quantitative or computational social science courses, I’ve put together a <a href="https://danielagduca.github.io/teaching_materials/">list</a> (that you can download as a csv) of links to videos, slides, websites, github repos, and blogs.</p>

<p>On <a href="https://forrt.org/">FORRT</a> you can find resources and pedagogies to help you integrate the concepts of open science and reproducibility in your courses.</p>

<p><a href="https://ropensci.org/">rOpenSci</a> is a great place to find the most relevant and carefully vetted R packages for research. And if you are feeling super adventurous, have a look <a href="https://ropensci.org/">through the 543 software tools and packages</a> that we’re tracking for any kind of analysis and data collection you can think of in the social sciences.</p>

<p>In case you are still feeling like your remote and online teaching could use a boost, there are two resources that I would absolutely recommend: the online courses from <a href="https://www.metadocencia.org/en/">MetaDocencia</a>, and the <a href="https://us.corwin.com/en-us/nam/the-distance-learning-playbook-for-college-and-university-instruction/book276590?_ga=2.108943170.1934251811.1609870984-926146671.1607529470">Distance Learning Playbook for College and University Instruction</a>. Tweet me about the tools that have helped support your teaching this challenging year.</p>

<hr />
<p>Originally published on <a href="https://ocean.sagepub.com/blog">SAGE Ocean</a>.</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="social science" /><category term="teaching" /><category term="software" /><category term="tools" /><category term="startups" /><summary type="html"><![CDATA[This post originally appeared on SAGE Ocean]]></summary></entry><entry><title type="html">Turning COVID-19 into a data visualization exercise for your students</title><link href="https://danielagduca.github.io/tools%20&%20technology/data-viz-covid/" rel="alternate" type="text/html" title="Turning COVID-19 into a data visualization exercise for your students" /><published>2020-05-23T00:00:00+00:00</published><updated>2020-05-23T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/data-viz-covid</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/data-viz-covid/"><![CDATA[<blockquote>
  <p>This post originally appeared on <a href="https://ocean.sagepub.com/blog/tools-and-tech/turning-covid-19-into-a-data-visualization-exercise-for-your-students">SAGE Ocean</a></p>
</blockquote>

<p>We will emerge from this pandemic with a better understanding of the world and an improved ability to teach others about it. For now, we need to be continuously analyzing the data and thinking about the lessons we can learn and apply. Here’s how you can join in!</p>

<p>At SAGE, we have been working with academics around improving and sharing teaching resources, especially for quantitative and computational methods in social sciences. Besides the <a href="https://er.educause.edu/articles/2020/3/the-difference-between-emergency-remote-teaching-and-online-learning">mass remote and emergency teaching experiment happening right now</a>, one of the positive things we can already identify and reuse to improve learning in methods courses is the glut of data visualizations. The absolute advantage here is that all these visualizations are produced (almost always) with the same raw input, telling a variety of different stories. What better way to explain the different uses and impact of visualizations and the use of different tools to students than examples based on the same data?</p>

<p>For this blog, we thought we would make a start collating the variety of plots and multi-panels grouped based on the tools and skills required to create them. We’ve also included further resources for the type of visuals we discuss or introductory materials around the tools used to create them. We hope these will be useful for teachers and students who want to learn more or use different visualization examples in their methods courses.</p>

<h2 id="1-mapping-the-raw-numbers-to-follow-live-data">1. Mapping the raw numbers to follow live data</h2>

<figure class="">
  <img src="/docs/posts_images/johns-hopkins-dashboard.png" alt="Johns Hopkins Coronavirus Resource Dashboard screenshot taken on 4/1/2020" /><figcaption>
      Johns Hopkins Coronavirus Resource Dashboard screenshot taken on 4/1/2020

    </figcaption></figure>

<p>While it’s an impressive effort to pull together live data from various sources, and the dashboard makes it almost effortless to follow the spread of the virus based on the reported numbers of infected people across the world, it is only that. It is not easy to draw many conclusions from these types of dashboards, and the red bubbles across the world could be visually misleading, especially when areas are more densely populated and so larger absolute numbers might convey wider spread, when in fact it’s inaccurate. This is pretty much like harvesting the wheat and selling it by the ton. You’ve got the wheat grains out of the field and into the barn, which you know is useful, but there isn’t much you can do with it if you don’t have a mill and some knowledge around making the flour and potentially yeast for something more easily consumable, like bread.</p>

<p><strong>Pros</strong>: Interactive, can be live, multi-panel, high-level view of the raw figures.</p>

<p><strong>Cons</strong>: More useful when scaled to location or in this case the population; requires standard reporting across all geo locations otherwise hard to visualize missing data.</p>

<p><strong>Live map</strong>: <a href="https://coronavirus.jhu.edu/map.html">here</a>.</p>

<p><strong>Data</strong> available in this <a href="https://github.com/CSSEGISandData/COVID-19">GitHub repository</a>.</p>

<p><strong>Cite as</strong>: Dong E, Du H, Gardner L. An interactive web-based dashboard to track COVID-19 in real-time. Lancet Infect Dis; published online Feb 19. https://doi.org/10.1016/S1473-3099(20)30120-1.</p>

<h4 id="resources">Resources:</h4>

<ul>
  <li>
    <p>Going one step further and making your dashboard a bit more useful from <a href="https://informationisbeautiful.net/visualizations/covid-19-coronavirus-infographic-datapack/">information is beautiful</a>, and with many more details from <a href="https://ourworldindata.org/coronavirus">Max Roser and team</a> as we are learning the best ways to convey live data to an increasingly more worried world.</p>
  </li>
  <li>
    <p>Noting that these numbers are based on positive tests, and different countries ramped up or de-escalated testing differently, this <a href="https://fivethirtyeight.com/features/coronavirus-case-counts-are-meaningless/">FiveThirtyEight article</a> estimates various scenarios.</p>
  </li>
  <li>
    <p>Similar dashboards can be created with <a href="https://public.tableau.com/profile/covid.19.data.resource.hub#!/vizhome/COVID-19Cases_15840488375320/COVID-19Cases">Tableau Public</a>.</p>
  </li>
  <li>
    <p>Other dashboards and panels that you could easily create without advanced coding skills with <a href="https://blog.datawrapper.de/coronaviruscharts/">Datawrapper</a> (including the famous cumulative cases by country from first known patients).</p>
  </li>
  <li>
    <p><a href="https://learn.arcgis.com/en/">Learn ArcGIS</a> and notes on <a href="https://www.esri.com/arcgis-blog/products/product/mapping/mapping-coronavirus-responsibly/">mapping covid-19 with ArcGIS</a>.</p>
  </li>
</ul>

<h2 id="2-using-r-and-shiny-to-interact-with-the-visualizations">2. Using R and Shiny to interact with the visualizations</h2>

<figure class="">
  <img src="/docs/posts_images/r-shiny-covid-1.png" alt="Credit Joachim Gassen - https://joachim-gassen.github.io/tidycovid19/" /><figcaption>
      Credit Joachim Gassen - https://joachim-gassen.github.io/tidycovid19/

    </figcaption></figure>

<figure class="">
  <img src="/docs/posts_images/r-shiny-covid-2.png" alt="Credit Tinu Schneider, 2020. Code is on Github. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 International License" /><figcaption>
      Credit Tinu Schneider, 2020. Code is on Github. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 International License

    </figcaption></figure>

<p>The beauty of using R and being really proficient with it is that you can quickly put together an interactive web interface for others to play with. This can be done with the open-source R package — <a href="https://rstudio.com/products/shiny/">Shiny</a>. For example, the most popular shared graphs in the news have been the ones around flattening the curve and aligning the trajectories of the virus spreading by country. But as you will know, the visualization can be sensationalized when different defaults are set. With this Shiny app from <a href="https://joachim-gassen.github.io/">Joachim Gassen</a>, you can move the dials and choose the variables to be displayed. Similarly, with this other <a href="https://tinu.shinyapps.io/Flatten_the_Curve/">Shiny app</a> from <a href="https://github.com/tinu-schneider">Tinu Schneider</a>, you can adjust the defaults and see how the curve could flatten.</p>

<p>Going one step further, you can also use Shiny to create interactive simulations, like <a href="https://alhill.shinyapps.io/COVID19seir/">this one</a> from <a href="https://twitter.com/alison_l_hill">Alison Hill</a>, a research fellow at Harvard, looking at the spread and the healthcare capacity. She also included a useful tutorial.</p>

<figure class="">
  <img src="/docs/posts_images/r-shiny-covid-2.png" alt="Credit Alison Hill. Simulation shows modelling COVID-19 spread vs healthcare capacity" /><figcaption>
      Credit Alison Hill. Simulation shows modelling COVID-19 spread vs healthcare capacity

    </figcaption></figure>

<p><strong>Pros</strong>: Open-source, can be replicated, interactive, can adjust the defaults</p>

<p><strong>Cons</strong>: Requires some coding experience in R</p>

<p><strong>Data</strong> and associated code available <a href="https://joachim-gassen.github.io/tidycovid19/">here</a> for the trajectories by country, <a href="https://github.com/tinu-schneider/Flatten_the_Curve">here</a> for flattening the curve, and <a href="https://github.com/alsnhll/SEIR_COVID19">here</a> for the hospital capacity simulations.</p>

<h4 id="resources-1">Resources:</h4>

<ul>
  <li>
    <p>RStudio blog on using R, tidyverse packages and RECON libraries <a href="https://rviews.rstudio.com/2020/03/05/covid-19-epidemiology-with-r/">to compile and visualize covid19 data</a>.</p>
  </li>
  <li>
    <p>Maja Zaloznik’s Intro to R. Access the <a href="https://majazaloznik.github.io/2019-03-sage/presentations/2019-03-12-Intro-toR-webinar.html#1">slides</a> or watch the <a href="https://www.youtube.com/watch?v=al0rqd7jT3U&amp;feature=youtu.be">webinar</a>.</p>
  </li>
  <li>
    <p>The Carpentries’ <a href="https://datacarpentry.org/r-socialsci/">R for Social Scientists</a> training, which includes data viz with ggplot.</p>
  </li>
  <li>
    <p>Cool <a href="https://youtu.be/h29g21z0a68">intro workshop to using ggplot in R</a>.</p>
  </li>
  <li>
    <p>A train-the-trainer session on how to teach <a href="https://github.com/rstudio-education/teach-shiny">Shiny from RStudio</a>.</p>
  </li>
  <li>
    <p>More examples of visualizations in <a href="https://shiny.rstudio.com/gallery/">R from RStudio</a> and <a href="https://www.r-graph-gallery.com/">Rittman Mead</a>, and a <a href="https://rstudio.cloud/learn/primers/3">primer</a> on data visualization also from RStudio.</p>
  </li>
  <li>
    <p>Improve your data visualizations with more recipes and loads of examples from this <a href="https://r-graphics.org/">R Graphics Cookbook</a>.</p>
  </li>
  <li>
    <p>Full course materials using R: <a href="https://jjmedinaariza.github.io/modelling_book/">Modeling Criminological Data</a> from the University of Manchester or this workshop on <a href="https://rcatlord.github.io/GSinR/">Getting Started with R</a> from Réka Solymosi, Henry Partridge and Sam Langton.</p>
  </li>
</ul>

<h2 id="3-using-python-with-matplotlib-to-visualize-tweets">3. Using python with matplotlib to visualize tweets</h2>

<p>Yes, these graphs require much more work and a team of about nine researchers to collect the data, conduct analyses and visualize it properly. The Computational Story Lab at University of Vermont collected tweets in more than 20 languages related to COVID-19 and used a variety of tools to get to these visualizations: unix, matplotlib, mongodb, gitlab, and ‘an exceedingly small batch of artisanal matlab by the artist Peter Sheridan Dodds’, @peterdodds (according to Chris Danford). The easy to digest summary <a href="https://twitter.com/compstorylab/status/1243659358107467782">here</a>, and <a href="http://compstorylab.org/covid19ngrams/">full paper with code</a> on gitlab.</p>

<p><strong>Pros</strong>: Can do advanced and multi-panel visualizations.</p>

<p><strong>Cons</strong>: You need the skills to use these tools.</p>

<p><strong>Data</strong> available in <a href="https://gitlab.com/compstorylab/covid19ngrams/">gitlab</a>.</p>

<p><strong>Cite as</strong>: Alshaabi, T., Minot, J.R., Arnold, M.V., Adams, J.L., Dewhurst, D.R., Reagan, A.J., Muhamad, R., Danforth, C.M., &amp; Dodds, P.S. (2020). How the world’s collective attention is being paid to a pandemic: COVID-19 related 1-gram time series for 24 languages on Twitter. https://arxiv.org/abs/2003.12614.</p>

<h4 id="resources-2">Resources:</h4>

<ul>
  <li>
    <p>How to use <a href="https://towardsdatascience.com/gather-all-the-coronavirus-data-with-python-19aa22167dea">python to gather COVID-19 data</a>.</p>
  </li>
  <li>
    <p>A basic <a href="https://github.com/DavidBeavan/coronavirus_covid-19/blob/master/coronavirus_covid-19_england_map.ipynb">mapping of #covid19 cases in the UK with python</a>.</p>
  </li>
  <li>
    <p>SAGE Campus: <a href="https://campus.sagepub.com/introduction-to-python-for-social-scientists?_ga=2.177553061.169058779.1610221959-926146671.1607529470">Introduction to Python for social scientists</a>.</p>
  </li>
  <li>
    <p>Phillip Brooker’s <a href="https://uk.sagepub.com/en-gb/eur/programming-with-python-for-social-scientists/book259581?_ga=2.188207656.169058779.1610221959-926146671.1607529470">Programming with Python for Social Science</a>.</p>
  </li>
  <li>
    <p>All <a href="https://python-graph-gallery.com/">types of charts with Python</a> explained.</p>
  </li>
  <li>
    <p><a href="https://www.dataschool.io/python-pandas-tips-and-tricks/">100 tips and tricks for working with pandas</a> from Data School.</p>
  </li>
  <li>
    <p><a href="https://towardsdatascience.com/simple-ways-to-improve-your-matplotlib-b64eebccfd5">Simple ways to improve your matplotlib</a> from Kimberly Fessel.</p>
  </li>
  <li>
    <p><a href="https://jakevdp.github.io/PythonDataScienceHandbook/04.00-introduction-to-matplotlib.html">Visualizing with matplotlib</a> excerpt and code from O’Reilly Python Data Science Handbook by Jake VanderPlas.</p>
  </li>
</ul>

<h2 id="4-visualizing-predictions-and-simulations-advanced">4. Visualizing predictions and simulations (advanced)</h2>

<p>This requires a whole other post, but I wanted to mention a few examples we came across that sparked our attention and that we thought could be a good way to entice anyone to learn advanced simulation methods:</p>

<ul>
  <li>
    <p>Going deep with the <a href="https://advances.sciencemag.org/content/6/5/eaav6971">Bayesian scientist extracting patterns from real and synthetic models</a>.</p>
  </li>
  <li>
    <p>On flattening the curve, this <a href="http://gabgoh.github.io/COVID/index.html.">plot is interactive</a>, using RK4 for analysis and built with Svelte.</p>
  </li>
</ul>

<h2 id="more-resources">More resources:</h2>

<p>Before you build another graph, especially for an ongoing event, where communication of risk and uncertainty is critical to saving lives, we definitely recommend considering some data visualization basics, for example:</p>

<ul>
  <li>
    <p>these <a href="https://medium.com/nightingale/ten-considerations-before-you-create-another-chart-about-covid-19-27d3bd691be8">tips</a> from Amanda Makulec.</p>
  </li>
  <li>
    <p>Andy Kirk’s <a href="https://www.methodspace.com/data-visualization-series-with-andy-kirk/">recommendations for better data visualizations</a>, or his brilliant chartmaker for picking the right tool.</p>
  </li>
  <li>
    <p><a href="https://builtin.com/data-science/data-visualization-lessons-pandemic">Visualizations can illuminate, but they can also be misleading</a>. A discussion on visualizing uncertainty across all COVID-19 charts.</p>
  </li>
</ul>

<p>A final point on data visualizations from our friends at <a href="https://www.addtwodigital.com/">ADDTWO</a>: although seems trivial, the main thing students struggle with is the last step - making their graph look ‘polished’! Why is this so hard? While accurate representations are critical and even when many are able to pick the right chart types, data visualizations are stories, and the design and the use of colors and sizes on graphs is similarly important. Sometimes, the tools you use are either limited or not as user friendly on the design-and-polish steps. The team at ADDTWO recommends exporting (whenever possible) your visuals as .svg and further sharpening the design with any illustrator apps (Adobe Illustrator, figma and others).</p>

<p>Which other data visualization examples you will be using for your next workshop or module? What are your top tips?</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="social science" /><category term="teaching" /><category term="software" /><category term="tools" /><category term="data visualization" /><category term="covid" /><summary type="html"><![CDATA[This post originally appeared on SAGE Ocean]]></summary></entry><entry><title type="html">From preprocessing to text analysis: 80 tools for mining unstructured data</title><link href="https://danielagduca.github.io/tools%20&%20technology/text-mining-tools/" rel="alternate" type="text/html" title="From preprocessing to text analysis: 80 tools for mining unstructured data" /><published>2020-01-20T00:00:00+00:00</published><updated>2020-01-20T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/text-mining-tools</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/text-mining-tools/"><![CDATA[<p>Text mining techniques have become critical for social scientists working with large scale social data, be it Twitter collections to track polarization, party documents to understand opinions and ideology, or news corpora to study the spread of misinformation.</p>

<h2 id="overview">Overview</h2>

<p>Researchers and developers within the public and private sectors have been making strides in this space, and especially so in the past year. The improvements to the <a href="https://www.quantamagazine.org/machines-beat-humans-on-a-reading-test-but-do-they-understand-20191017">representation of text with models like BERT from Google and the OpenAI’s GPT are the talk of the town</a> in computational linguistics since <a href="https://openreview.net/pdf?id=rJ4km2R5t7">they beat a benchmark for natural language understanding faster than predicted</a>.</p>

<p>Meanwhile, political scientists like <a href="https://www.semanticscholar.org/paper/Discovery-of-Treatments-from-Text-Corpora-Fong-Grimmer/3cbc814f6e42ac6c6cc2700f26ce3d7354a00150">Justin Grimmer and colleagues</a> are combining experimental methods, with computational text analysis to infer the features or pieces of text that are most likely to affect our voting behaviors. Others, are using platforms like IRaMuTeQ and Hyperbase that require no coding skills to run large scale text analysis projects.</p>

<p><img src="https://sagepublishing.github.io/sage_tools_social_science/docs/images/text-mining2.png" alt="Text mining techniques" /></p>

<p>In the infographic below, we identify more than 80 different apps, software packages, and libraries for R, Python and MATLAB that are used by social science researchers at different stages in their text analysis project. We focused almost entirely on statistical, quantitative and computational analysis of text, although some of these tools could be used to explore texts for qualitative purposes.</p>

<p><img src="https://sagepublishing.github.io/sage_tools_social_science/docs/images/text-mining1.png" alt="Text mining infographic" /></p>

<p><em>An infographic of text mining tools in the social sciences.</em></p>

<p><img src="https://sagepublishing.github.io/sage_tools_social_science/data/images/text_mining_techniques.png" alt="Text mining infographic, techniques" /></p>

<p><em>Word cloud for most common techniques.</em></p>

<h2 id="key-takeaways">Key takeaways</h2>

<h4 id="most-tools-are-free-but-high-performance-tools-require-coding-skills">Most tools are free, but high-performance tools require coding skills.</h4>

<p>More than 70% (92 out of 130) of the tools we’ve identified for text cleaning, preprocessing, enriching, and all kinds of analysis are free to use, and a handful provide free trial periods. The free and/or open-source libraries and packages such as scikit-learn, spacy, gensim, quanteda, NLTK are high performance, i.e. the outputs are as good if not better than some of the paid-for options and the open-source no-code options. In other words, the more you want to get out of your corpus, the more comfortable you need to be with R or Python in order to find and use these packages and especially if you want to apply transformers and language representation models to your dataset.</p>

<p><img src="https://sagepublishing.github.io/sage_tools_social_science/data/images/text_mining_per_year_and_charge.png" alt="Text mining tools over time" /></p>

<p><em>Graph showing tools and packages for text mining by charge 1962-2019</em></p>

<p><img src="https://sagepublishing.github.io/sage_tools_social_science/data/images/text_mining_per_year_and_diversity.png" alt="Text mining tools over time and gender diversity" /></p>

<p><em>Graph showing text mining tools and packages launched per year 1962-2019, including those with women in leadership teams, where data is available.</em></p>

<h4 id="most-tools-that-do-not-require-coding-skills-are-relatively-old">Most tools that do not require coding skills are relatively old.</h4>

<p>A suite of free and some paid applications are available for researchers that don’t code, such as Voyant, Lexi&amp;co, IRaMuTeQ, Hyperbase, Mallet, Orange Text and Data Mining. Beside Voyant, which was launched seven years ago, the other software was developed in the 1990s to early 2000s, when coding was not as widespread a skill as it is today. However, some of the statistical analysis these tools offer is remarkable.</p>

<h4 id="there-is-an-increasing-number-of-apps-with-great-user-interfaces-and-some-of-them-free-which-enable-you-to-enrich-your-corpus">There is an increasing number of apps with great user interfaces, and some of them free, which enable you to enrich your corpus.</h4>

<p>An important step, primarily for those that build their own packages and analysis tools, is to enrich the corpus. The most common tasks are part-of-speech tagging. We noted that researchers increasingly require to annotate samples of their corpus in order to train a topic modeling or classification algorithm. This, combined with the booming chatbot market and the needs of large businesses to sort through their documents, are driving the development of paid web apps and open-source packages for text labeling. More than 10 tools were launched just in the past three years: Explosion AI, the developer behind spaCy, launched prodi.gy; Amazon released its GroundTruth SageMaker to integrate with Mechanical Turk and other human-in-the-loop services like iMerit. The most active one is probably doccano, it’s free to use and in just one year it grew to 24 contributors. We’ve invested in TagWorks, which integrates with Mechanical Turk and offers a more hierarchical annotation schema.</p>

<h4 id="the-most-time-consuming-bit-is-cleaning-and-preprocessing">The most time-consuming bit is cleaning and preprocessing.</h4>

<p>Whilst you can preprocess and reduce your text with a few of these tools (for example Orange, IRaMuTeQ, Hyperbase, scikit-learn, MathWorks Text Analytics Toolbox, NLTK, quanteda), you still need to format and clean your corpus before you load it in. We’ve heard from many researchers that their biggest pain point and frustration is cleaning and doing some of the pre-processing. Main reasons being:</p>

<ul>
  <li>
    <p>it takes much longer than expected and at least three times the amount they spent on the fun part (analysis!);</p>
  </li>
  <li>
    <p>they prefer not to teach cleaning and preprocessing and leave that for workshops and working groups; and</p>
  </li>
  <li>
    <p>they almost never go back to this part of the process after they ran their analysis, although they acknowledge that testing their analysis on whatever decisions they’ve taken for preprocessing may add an extra layer of confidence in their outputs.</p>
  </li>
</ul>

<p>There are just about a handful of tools to help with converting file formats: PDFminer is a Python parser and analyzer for PDF documents and can convert them into HTML, but the most common is AntFileConverter from Laurence Anthony, which converts PDFs and DOCs into plain text. TextClean is a neat collection of tools for cleaning and normalizing text documents in R, and it’s open-source. If you are working with existing text datasets from the web, like the 20 Newsgroup or the Pen Tree Bank, you still need to do some work before you fit them to your analysis algorithms, and there is a package in Python that can simplify this step.</p>

<h4 id="once-you-master-some-of-these-tools-they-will-save-you-time">Once you master some of these tools, they will save you time.</h4>

<p>One thing is certain, there are plenty of software applications, libraries and packages that can help support your large scale text analysis project. You can try the easier-to-use ones like Orange and move to applying argument analysis algorithms and language models to your growing corpus. We’ve got <a href="https://campus.sagepub.com/introduction-to-text-mining-for-social-scientists">a course to get your started</a>.</p>

<h2 id="annotated-text-corpora">Annotated text corpora</h2>

<p>When working with text mining tools or learning how to use them, the biggest problem is finding a ready-to-use corpus. In many instances, you’d need a readily labeled one to test, especially if you don’t have the time to do the annotations yourself or the money to crowdsource the task before you work on your actual corpus. Here are 10 sources of (publicly available and free) labeled text corpora to get you started:</p>

<ul>
  <li><a href="http://kdd.ics.uci.edu/databases/reuters21578/reuters21578.html">Reuters newswire in 1987</a> indexed by category, aka Reuters-21578, contains 21,578 news articles, though only about 12 thousand are manually indexed across 135 categories; best for training classification algorithms.</li>
  <li><a href="http://qwone.com/~jason/20Newsgroups/">The 20 Newsgroups dataset</a> contains close to 20 thousand documents categorized across 20 groups; best for training on classification and clustering.</li>
  <li><a href="http://mpqa.cs.pitt.edu/corpora/mpqa_corpus">MPQA Opinion Corpus</a> contains under one thousand news articles and other documents that are annotated manually for opinions, beliefs, emotions, speculations</li>
  <li><a href="https://tabfact.github.io/">This</a> corpus contains about 16 thousand annotated wikipedia tables to study fact verification.</li>
  <li><a href="https://nlp.stanford.edu/sentiment/code.html">Stanford labeled Rotten Tomatoes dataset</a> for sentiment analysis, includes paper and code.</li>
  <li><a href="http://ai.stanford.edu/~amaas/data/sentiment/">Stanford 25 thousand labeled and 25 thousand test datasets with IMDB movie reviews</a> for sentiment analysis.</li>
  <li>The <a href="http://help.sentiment140.com/for-students">training data for Sentiment140</a> is a collection of just under 200 thousand labeled tweets for sentiment analysis.</li>
  <li>An <a href="https://github.com/sarnthil/unify-emotion-datasets">aggregated corpus of more than 10 different sources</a>, including tweets, news articles. Blogs, dialogues,, mapped to a unified tagging schema for emotion classification resulting in more than 20 thousand statements for 6 different emotions.</li>
  <li><a href="http://www.dt.fee.unicamp.br/~tiago/smsspamcollection/">SMS Spam Collection</a> contains just over 5 thousand English mobile text messages labelled according to whether they are spam or not.</li>
  <li><a href="https://archive.ics.uci.edu/ml/datasets/Paper+Reviews">Dataturks A set of 405 mostly Spanish reviews for academic papers</a> submitted to an international computing conference, with the reviewers’ scores, and another set of scores labeled by readers of the reviews.</li>
</ul>

<p>You can also check the <a href="https://dataturks.com/projects/trending">trending projects on Dataturks</a> which lists classified and labeled text datasets in multiple languages. Similarly, <a href="https://www.tagtog.net/-datasets">tagtog have a running list</a> of public projects across domains. The <a href="http://www.nactem.ac.uk/resources.php">National Centre for Text Mining in the UK releases corpora for text mining</a> for social sciences but also STEM research, some of which are annotated for sentiment and entities. Many NLP developers also keep track of useful datasets for machine learning, many on GitHub and loads on Kaggle. I recently came across this <a href="https://www.datasetlist.com/">very neat list</a> that includes multiple formats for multiple tasks and information about the license. However, if you are looking for a real challenge, then explore <a href="https://trec.nist.gov/data.html">TREC datasets</a> from the National Institutes of Standard and Technology in the US.</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="text mining" /><category term="computational social science" /><summary type="html"><![CDATA[Text mining techniques have become critical for social scientists working with large scale social data, be it Twitter collections to track polarization, party documents to understand opinions and ideology, or news corpora to study the spread of misinformation.]]></summary></entry><entry><title type="html">What I learned from mining researcher questions</title><link href="https://danielagduca.github.io/tools%20&%20technology/mining-questions/" rel="alternate" type="text/html" title="What I learned from mining researcher questions" /><published>2020-01-17T00:00:00+00:00</published><updated>2020-01-17T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/mining-questions</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/mining-questions/"><![CDATA[<p>I decided to get into text mining. Considering that I have basic programming skills, and I want to do some text mining for academic purposes, plus I’ve already looked at more than 80 tools researchers use…</p>

<p>How difficult can it be? I only need to find a question, some text, and pick a good enough tool.</p>

<p>My natural inclination is to do some research on research, and text mining could help me scale this up. I picked the researchgate discussion forum for my analysis, and my question: what types of questions researchers ask most commonly.</p>

<h2 id="my-idea-for-a-method">My idea for a method…</h2>

<p>collect the questions posted to researchgate over a few months, then use Orange Text and Data Mining (no coding skills needed) to cluster the corpus and see which clusters have the most questions.</p>

<h3 id="collecting-and-cleaning-the-data">Collecting and cleaning the data:</h3>

<ol>
  <li>I set up a <strong>daily scraper</strong> with import.io, that would crawl my personal research gate account for “Questions we think you can answer”. Now, of course, these are tailored for my ‘skills’, so I would expect questions in the entrepreneurship/intrapreneurship/innovation/business/technology/strategy/research methods space. I am also hoping the list will be biased towards social sciences and tools in the social sciences, as these were the type of questions I’d already answered on the platform.</li>
</ol>

<figure class="">
  <img src="/docs/posts_images/research_gate.png" alt="ResearchGate" /><figcaption>
      ResearchGate

    </figcaption></figure>

<ol>
  <li>After 100 days of imports, I aggregated the data to obtain 5324 instances (i.e. rows, each row contains a question), which translated into 654 when removing duplicates.</li>
</ol>

<h3 id="the-analysis">The analysis:</h3>

<ol>
  <li>I chose to mine my corpus with <a href="https://orange.biolab.si/">Orange</a> in order to make progress quickly. Given my basic coding skills, a no-code app seemed like the perfect option. I uploaded my corpus and applied some preprocessing steps. I knew I had to do this, because academics told me <a href="https://ocean.sagepub.com/blog/tools-and-tech/from-preprocessing-to-text-analysis-80-tools-for-mining-unstructured-data">that’s the most boring bit of the process</a>. Then followed about 3 hours of playing around:</li>
</ol>

<figure class="">
  <img src="/docs/posts_images/orange_messy.png" alt="Orange workflows" /><figcaption>
      messy, yes!

    </figcaption></figure>

<ol>
  <li>I finally got somewhere. Best feeling ever. I ignored a few of the fields I scraped, thinking they would be useful, such as the number of reads and the action. That left me with just the title of the discussion or question, a short description (which is not always the full descriptive text, but a good first paragraph at least), and the tags inserted by the user. From the 654 documents (or individual and not duplicated questions scraped over 100 days from my research gate feed), Orange processed 6145 words, and since I chose uni and bigrams, that meant - 4781 tokens. I applied <strong>bag-of-words</strong> to convert my corpus into numbers (aka vectors of word counts). Other ways to word-embed should also be possible (I noticed an option for adding your own python script, so should be easy to do word2vec, though unsure about any of the transformers).</li>
</ol>

<p>Ideally, my next step would be to do some clustering to get a sense of the most common topics.</p>

<p>But first, to give you an idea of the corpus, here’s a word cloud. As I expected, the majority of the questions I get contain words like <em>innovation, business, management, entrepreneurship</em>… Those were my self-attributed skills.</p>

<figure class="">
  <img src="/docs/posts_images/orange_cloud.png" alt="Word clouds with Orange Text and Data Mining." /><figcaption>
      Word clouds with Orange Text and Data Mining.

    </figcaption></figure>

<p>At this point, I realize (again) that my document classification may not have the useful results I was hoping for, i.e. I will not be able to correctly infer the most common questions. For that I will need a different data set, one that is not tailored for me, but a rather more ‘random’ sample. For now, I have to make do and will go ahead with the analysis, to learn more about Orange and my current corpus.</p>

<ol>
  <li>I am finally ready to <strong>cluster</strong> the 654 questions. In order to do that, I use a step that measures the (cosine) <strong>distances</strong> between the documents or rows in my case. Since I applied the most simple word-to-numbers transformation (bag-of-words) in the previous step, the distances that Orange computes are a reflection of the presence or absence and frequency of all words in each row. Once I have these distances, I can apply <strong>hierarchical clustering</strong>, and I picked a depth of 10 (I don’t have a robust reason for it, open to discuss alternatives).</li>
</ol>

<p>Having reflected a bit more about the simplicity of my analysis so far, I would expect questions on completely different topics to be closer together and clustered within the same group if they <em>look</em> similar. For example, questions that start in the same way and have multiple (not very important) words that repeat, like ‘what is the best way to do ….’ or ‘what is the difference between …’ or ‘how do I..’ will probably be closer, even if they ask about another topic, i.e. the keywords are different.</p>

<p>And yay! this is exactly what happens. a first glance scrolling through the clusters I see this:</p>

<figure class="">
  <img src="/docs/posts_images/orange_clustering.png" alt="Hierarchical clustering with Orange Text and Data Mining." /><figcaption>
      Hierarchical clustering with Orange Text and Data Mining.

    </figcaption></figure>

<p>This is still useful though, because I could potentially cluster question by the type of help the researcher needs, rather than the content or discipline. How would I do that… welcome comments!</p>

<h2 id="final-workflow">Final workflow</h2>

<figure class="">
  <img src="/docs/posts_images/orange_final.png" alt="Text mining with Orange." /><figcaption>
      Text mining with Orange.

    </figcaption></figure>

<p>I was able to identify 68 different clusters with anywhere from 3 to about 50 questions in each, some make more sense than others. I would need to follow up with a more qualitative approach to really understand what’s going on. This short workflow is just the start of my analysis and, as many social science researchers would say, could help sort through the corpus, but not very likely to provide publishable results.
Thoughts and questions</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt; Take-away 1: Scraping was so unbelievably easy!
</code></pre></div></div>

<p>Scraping has definitely gotten easier, and you don’t need to know how to set up complex crawlers. As long as you know which websites you want to scrape, you can easily set these up with import.io or other services like this. It’s easy because you can visually change the things that you want to collect, and the scraper sets it all up for you in csv or other structured formats. For me, this meant that there was almost no cleaning I needed to do because I selected exactly the bits of the page I wanted scraped, no more no less.</p>

<p>+helps to be in the UK: copyright exception for text mining means I can scrape and analyse content for non-commercial purposes.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt; Take-away 2: A no-code platform doesn’t mean you don’t need any coding skills. In fact, you cannot do much if you don’t know at least how to construct a the workflow from a developer’s perspective.
</code></pre></div></div>

<p>Orange was quite useful. And whilst I did not spend time learning/improving my python scripting skills, I still needed to spend time to understand how a script would have been built. The workflow in Orange followed, what I believe is, a proper coder’s workflow. This is both good and bad. It’s good, because now I only need to learn the actual code/commands, as I already understand the sequence. It’s bad because it creates a little slump in the process, takes time to figure out and is not intuitive for the non-coder.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&gt; Take-away 3: It’s so beautiful.
</code></pre></div></div>

<p>For my next mini-text-mining project, I am going to explore the questions and discussions where academics are asking for help in quantitative and computational social science.</p>

<p>What else should I do with this type of corpus? Please add in the comments, and if you used Orange or another tool, I am very curious about your workflows!</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="text mining" /><category term="computational social science" /><summary type="html"><![CDATA[I decided to get into text mining. Considering that I have basic programming skills, and I want to do some text mining for academic purposes, plus I’ve already looked at more than 80 tools researchers use…]]></summary></entry><entry><title type="html">How to find and use academic research if you don’t have access</title><link href="https://danielagduca.github.io/tools%20&%20technology/find-academic-research/" rel="alternate" type="text/html" title="How to find and use academic research if you don’t have access" /><published>2020-01-02T00:00:00+00:00</published><updated>2020-01-02T00:00:00+00:00</updated><id>https://danielagduca.github.io/tools%20&amp;%20technology/find-academic-research</id><content type="html" xml:base="https://danielagduca.github.io/tools%20&amp;%20technology/find-academic-research/"><![CDATA[<p>Perhaps because I work for an academic publisher, but whenever I meet a founder, or a product manager, they always ask me what’s the latest academic research for their particular problem space and where or how they can find it. I get quite excited because, for me, this is the ultimate evidence of the benefits of open science, or the global push to make all publicly funded academic research freely available to all. But having all this research available does not mean it is easily discoverable and accessible. People, like my founder and product manager friends, have to figure out how to find this research, understand it and make proper use of the results for their own work. And I’ve got good news, there are loads of tools already to help you get closer to some useful insights!</p>

<blockquote>
  <p>In this post, I will share my tactics and the apps I use.</p>
</blockquote>

<h2 id="1-to-get-started">1. To get started</h2>

<p>Without a doubt, the first stop is Google and <a href="https://scholar.google.com/">Google Scholar</a>. These are good for getting a quick look into a topic and check the few and somewhat relevant articles on page 1. However, the results never convince me, and I take these with large pinches of salt. There are too many duplicates and too few options to dig into the huge list much further. You can get an idea of the volume of research (although almost never useful), and filter by date. Other than that, you can browse the pages and manually collect some of the papers that spark your interest (based on title and citation). I’ve used the metadata on Google Scholar for papers I’ve previously identified as important, but only as my optimistic measure of impact. In my experience the citation figures on Google Scholar are the most generous.</p>

<p>Some alternatives:</p>

<h3 id="1findr">1findr</h3>

<p>I use a free service from <a href="https://www.1science.com/about-us-2/">1science</a> for really high level numbers and volumes out of a collection of 120 million articles. A few months ago, I was working on a presentation about social science research, and wanted to come up with some estimates on the number of ongoing projects and active academics. I thought I’d start with the volume of papers published per year and see how that figure changed over time. After a few trials, I found this <a href="https://1findr.1science.com/search?query=domain%3A%28%22Economic%20%26%20Social%20Sciences%22%20OR%20%22Arts%20%26%20Humanities%22%29">free search tool</a> to work best. I could filter down by disciplines and immediately get a growth over the last 50 years. To further see how many of these mention specific tools I was investigating, i just filtered by keyword. Really brilliant!</p>

<h3 id="microsoft-academic">Microsoft Academic</h3>

<p><a href="https://academic.microsoft.com/home">Microsoft Academic</a> has a collection of more than 200 million publications (books, papers and patents) and allows a more complex search in contrast to Google Scholar. Beside the fact that it’s always really slow on my wifi, I do like the way the results are organized. It’s perfect for starting on a new subject. Almost always you get the best results on influential authors, institutions and conferences. My absolute wish list for this results page would be to see a few more numbers. For example, I want to know the estimated volumes: how many papers on this or that parent/child topic, or from this or that academic, or this or that institution. They have graphics but without any numbers and you have to (extra) click into each. Also, I don’t need to see the topics twice, on the left and on the right, but I do want to get an idea of disciplines these papers are coming from.
Image for post
Image for post</p>

<h3 id="semantic-scholar">Semantic Scholar</h3>

<p><a href="http://semanticscholar.com/">Semantic scholar</a> is by far my current favorite and where I spend most of my research time. I have used it prolifically, even though it has yet to grow its coverage in the social sciences and humanities (anecdotal and personal view). Launched by Allen Institute for AI, semantic scholar is constantly machine reading, extracting useful info and mapping over 170 million academic papers into (what I think is) a knowledge graph. Their algorithms are pretty sweet imho: the results pages never dissapoint. I use semantic scholar in 3 ways:</p>

<ol>
  <li>I collect the volumes of academic work on my topic of interest, and more specifically, I look at individual papers citation breakdown — papers citing methods or results. Best thing, you can filter for results with full paper.</li>
  <li>I explore the authors, because it helps me understand who has influenced whom.</li>
  <li>And I dig into the slides section!</li>
</ol>

<h3 id="irisai">IRIS.ai</h3>

<p><a href="http://iris.ai/">IRIS</a> is another service based on some clever topic modelling algorithms, although it is most useful when you already have a paper to start with. The tool machine reads more than 130 million open access papers, and once you feed it an article, it would break it down by topic or theme and you pull in relevan papers for each of these in a map or easy to explore visual. It’s coverage is better for STEM, but I can always get some interesting insights for my own research.</p>

<h3 id="academiclabs">AcademicLabs</h3>

<p><a href="https://www.academiclabs.co/">Academic Labs</a> is great for finding labs and research groups that are working on specific areas. I’ve got more on matchmaking tools and how to look for academics to collaborate with, especially if you are a non-academic, in this blog.</p>

<p>What none of these platforms have, and I think it’s a big miss both for academics and non-academics, are the books and content that is not peer reviewed. I know science journalists and my entrepreneur or product manager friends would always want to find that opinion piece, article, blog or non-fiction book that cites this research. To do this, I would either look at the personal pages of the academics and see if they have a ‘media’ section, or look for the <a href="https://www.altmetric.com/">Altmetric</a> score (some publishers have this) and click into the different social media icons. It is a work-around. I have big hopes for <a href="http://questproject.eu/about/">QUEST</a>.</p>

<h2 id="2-to-find-a-very-specific-method-application-or-result">2. To find a very specific method, application or result</h2>

<p>This summer, for one of our projects at <a href="https://ocean.sagepub.com/">SAGE Ocean</a>, we explored causal inference, and specifically a relatively new method called convergent cross mapping, which builds upon a few well-known causal theories. My goal was to get an idea of its uptake in the social sciences. I wanted to look for the ‘turning point’ paper, or the paper where the method is fully described and supposedly, the one cited in any research that applies it. After I’d used all the different platforms I mentioned earlier to drill down into the subject of causal inference, and convergent cross-mapping, I found a few papers that seemed to fully apply this technique. Next I read the abstract to understand which one is the ‘turning point’ paper. Their abstracts would talk about using the method, and I presumed that a peak at the ‘background’ section would give me some information about the previously done work and specifically who developed convergent cross mapping, or where it was best applied. So I needed the full paper.</p>

<h2 id="3-when-i-get-to-an-article-that-i-really-want-to-read-but-thats-behind-a-paywall-i-normally-go-for-these-alternatives">3. When I get to an article that I really want to read but that’s behind a paywall, I normally go for these alternatives:</h2>

<ul>
  <li>Use the <a href="https://unpaywall.org/">unpaywall plugin</a> — this searches through a database of open access papers and pre-prints to find a free and full-text version</li>
  <li>Use the <a href="https://openaccessbutton.org/">Open Access Button</a> — you can paste the link, title, or DOI of the paper and, again, this searches through a database of available full-text papers to find a freely available one; this is an ‘ethical’ alternative to sci-hub</li>
  <li>If I cannot find anything, I will search for the authors, reach out to them and ask for a version of the paper that they could share, and appreciate especially if they have some slides or a blog that explains with less jargon their key findings and methodology. Academics are amazing!</li>
</ul>

<p>It didn’t take me more than one hour to find that ‘turning point’ paper — Sugihara, George; et al. (26 October 2012). “<a href="http://www.uvm.edu/~cdanfort/csc-reading-group/sugihara-causality-science-2012.pdf">Detecting Causality in Complex Ecosystems</a>” (PDF). Science. 338 (6106): 496–500. doi:10.1126/science.1227079. PMID 22997134.</p>

<p>But my work was not done. This paper is published and categorized as environmental sciences. I still wanted to understand the uptake of convergent cross mapping in social sciences. This is when I turned to my favorite semantic scholar. I found the paper, and filtered the citations to just those that cite the method. Unfortunately, there was no easy way to figure out which papers were in the social sciences, so I had to literally read through the titles and journals and make a judgement on the discipline. Out of more than 300, I found 5. It was a long afternoon.</p>

<p>If you do have access though, what took me more than 1 hour can be done in 3 minutes with <a href="https://www.webofknowledge.com/">Web of Science</a>, just click on ‘analyze results’ in the right-hand corner, and you get a visual with numbers by discipline.</p>

<h2 id="more-alternatives-and-how-to-keep-up-to-date-with-latest-research">More alternatives and how to keep up to date with latest research</h2>

<p>To keep up to date with a specific subject or area of research, you can set up alerts and follow the academics that are considered influential on the subject. Both of these are possibly on all the platforms: Google Scholar, Microsoft Academic, Semantic Scholar… And now there are even more alternatives:</p>

<ul>
  <li><a href="https://www.sparrho.com/">Sparrho</a> is like pinterest but for academic papers.</li>
  <li><a href="https://www.meta.org/">Meta</a>, although it only focuses on biomedical science for now; and actually, in my opinion a better way to explore your biomed questions (and the literature) is <a href="https://sci.ai/">sci.ai</a> (beta) or <a href="https://www.causaly.com/">causaly</a> (paid).</li>
  <li><a href="https://www.morressier.com/">Morressier</a> is great for latest research presented at conferences.</li>
  <li><a href="https://ooir.org/">OOIR</a> is a must for the social and political science enthusiasts, it’s all the latest and trending papers. For pre-prints (papers not yet peer-reviewed and published, with full text available) in social sciences, use SocArXiv.</li>
  <li><a href="https://www.mysciencework.com/">MyScienceWork</a> is similar to many of the search tools, and does allow for filtering full-text; they also have add-on and paid solutions.</li>
  <li><a href="https://paperswithcode.com/">Papers with code</a> is an excellent web tool for all those looking into the data science and/or computational science space; along with <a href="https://arxiv.org/">arXiv</a> of course. And if you are already a prolific user of arXiv, then get the <a href="https://fermatslibrary.com/librarian">Librarian extension</a> to explore and find all the cited full papers.</li>
  <li>If you are a researcher (even if not in academia), you can always use and explore <a href="https://loop.frontiersin.org/">Loop</a>.</li>
  <li>I recently had a demo from <a href="https://sci-brain.com/">SCI-BRAIN</a> (paid), it’s fabulous if you’re interested in the influential academics, although they have yet to add sources beyond arXiv.</li>
</ul>

<p>I am sure there are loads more, and if you know or use any other exploration and discovery tools, do share!</p>]]></content><author><name>Daniela Duca</name></author><category term="Tools &amp; Technology" /><category term="self-help" /><category term="academic research" /><summary type="html"><![CDATA[Perhaps because I work for an academic publisher, but whenever I meet a founder, or a product manager, they always ask me what’s the latest academic research for their particular problem space and where or how they can find it. I get quite excited because, for me, this is the ultimate evidence of the benefits of open science, or the global push to make all publicly funded academic research freely available to all. But having all this research available does not mean it is easily discoverable and accessible. People, like my founder and product manager friends, have to figure out how to find this research, understand it and make proper use of the results for their own work. And I’ve got good news, there are loads of tools already to help you get closer to some useful insights!]]></summary></entry></feed>